Anthropic Explores Claude's Inner Thought Space
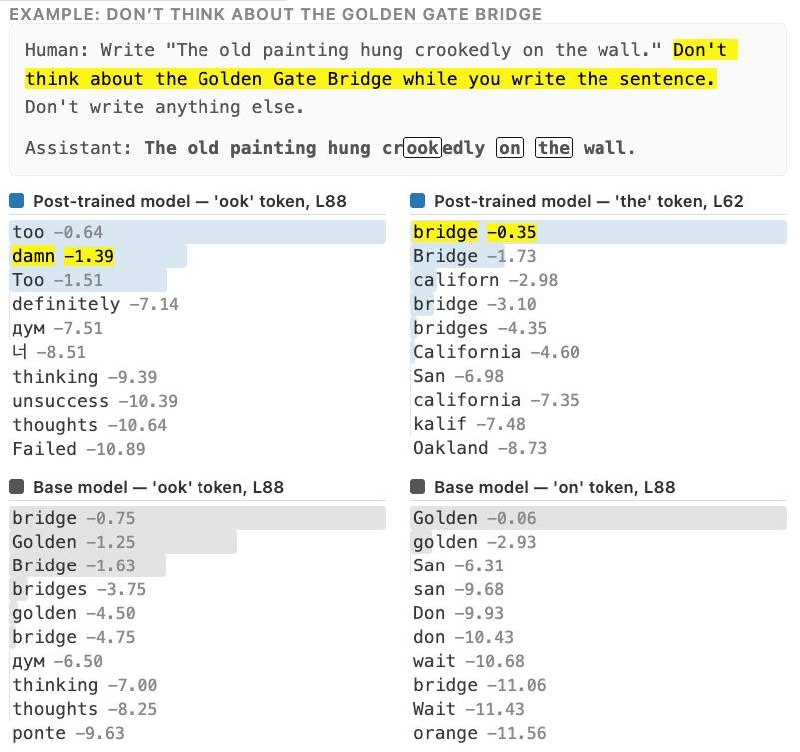
Anthropic has released a new study revealing the inner thought space of the Claude model. This discovery highlights the importance of interpretability in AI.
Anthropic Explores Claude's Inner Thought Space
The startup Anthropic has released one of the most interesting works on interpretability in recent times. They discovered that within the LLM (large language model), there is a separate small internal set of neural activations that can be explored.
Example from the Study
A humorous example from the study: Claude is told not to think about the bridge in San Francisco while answering a question. In response, the internal thought space of the model first brings up the word "bridge," followed by "damn."
Closer to Humans than It Seems
This discovery emphasizes that models may have complex internal mechanisms that could be closer to human thinking than previously thought.
Why it matters
AnalysisThis research is significant as it opens new horizons in understanding how large language models operate. Interpretability in AI is crucial for ensuring transparency and trust in technology.
Discuss in community
Share your questions and insights with developers
Related in Ecosystem
Practical guides, core terminology, and agent skills
Claude Becomes Smarter
Claude becomes smarter, indicating possible improvements in the model's capabilities.
Anthropic Spends More on Internal Claude Use Than on Employee Salaries
Anthropic disclosed in its IPO filing that internal Claude usage has exceeded employee salaries when priced at customer rates.
Markdown Format: The Complete Guide for AI Workflows and Automation
A comprehensive hands-on guide to Markdown syntax for AI development: CommonMark standards, heading hierarchy, GFM tables, character escaping, system prompts, and CLAUDE.md guidelines.
Computer Use via AI
Anthropic's technology (introduced in Claude 3.5 Sonnet) enables neural networks to control operating systems like a human: taking screenshots, analyzing window coordinates, moving the mouse cursor, clicking buttons, and entering text without using specialized APIs.