Qwen3.8-Omni-Flash Released: Multimodal Model with 1M Token Context
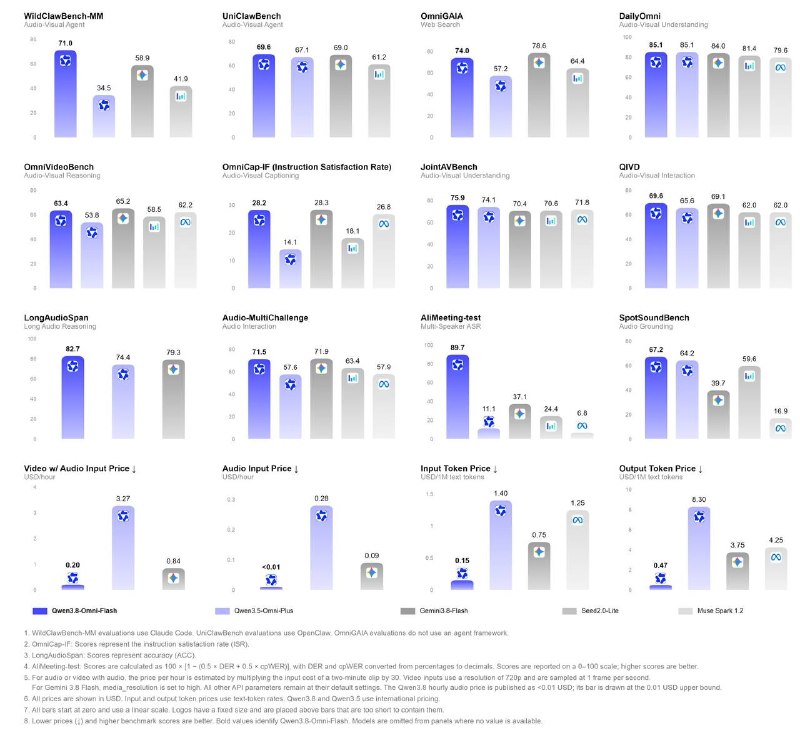
Qwen has launched Qwen3.8-Omni-Flash, a multimodal model with a 1 million token context window, improved video understanding, and significantly lower costs for audio and video processing.
Qwen3.8-Omni-Flash Released
Developers call it the first multimodal model in the lineup built around agentic capabilities. It understands text, images, audio, and video as input, with a context window of 1 million tokens.
Video understanding and processing have been significantly improved: the model much better comprehends long videos, can generate deep research reports or captions based on them, and does not hallucinate timecodes. Meanwhile, text capabilities are maintained at the level of the standard Qwen-3.8 Flash.
Overall, this model is designed as an intermediate link for a future full pipeline for scenarios such as video editing, translation, movie commentary, content creation, etc.
Compared to the previous Qwen3.5-Omni-Flash, token consumption has also decreased significantly, and the price has become lower:
- Audio processing is 98% cheaper;
- Audio-video processing is more than 93% cheaper.
This is achieved with performance comparable to Gemini 3.8 Flash.
The model is already available in the API and in Qwen Chat.
Why it matters
AnalysisThis release is crucial for AI developers working with multimodal data, offering high performance and agentic capabilities at a fraction of the previous cost, particularly for video-heavy applications.
Discuss in community
Share your questions and insights with developers
Related in Ecosystem
Practical guides, core terminology, and agent skills
Google Gemini Pro (Model with Infinite Context)
The flagship working model from Google DeepMind featuring a record context window of over 2 million tokens. Capable of analyzing entire books, lengthy videos, and massive codebases in a single query.
GPT-6 Astra reportedly edits another AI model's weights without retraining
GPT-6 Astra is claimed to modify only 0.016% of Qwen3.5-0.8B's weights without gradients or retraining, improving reasoning, math results, and instruction following.
Gemini Flash & Pro (Google Gemini)
A family of multimodal models from Google DeepMind that combines a record context window (up to 2 million tokens), extreme generation speed (over 150 tokens/sec), and native perception of video and audio.
MIT researchers show LLMs can read and edit neural network weights without training
MIT CSAIL researchers introduced Weight-Space Programming, where an LLM directly reads and modifies model weights; Astra improved Qwen3.5-0.8B math scores without gradient descent or fine-tuning.