Google Releases Multimodal EmbeddingGemma 2
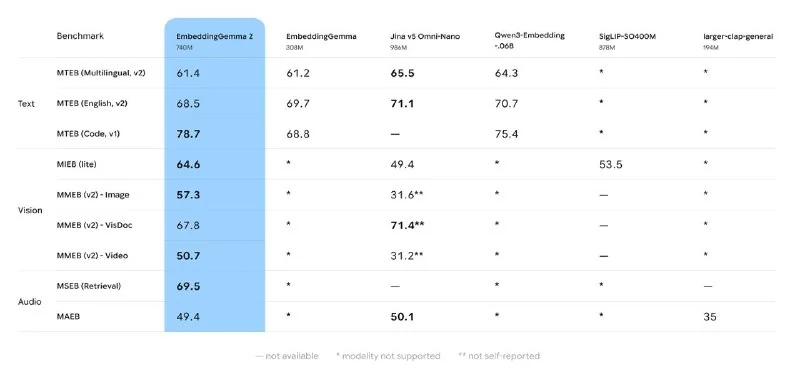
EmbeddingGemma 2 maps text, code, images, video, and audio into a single vector space, allowing mixed inputs.
Google has released the multimodal model EmbeddingGemma 2. The first version worked only with text, while the second is built on Gemma 4 and maps text, code, images, video, and audio into a single vector space. Mixed data can now be used as input.
The model has 740M parameters, but it is modular. The text part takes 270M, while image and audio encoders are loaded separately as needed. The context window increased to 8K tokens, which is about 5.5 minutes of audio or 29 images at once.
On text tasks, quality remained at the level of the first version, while code performance improved noticeably. Google claims the best result among multimodal embedding models up to 1B parameters.
Weights are open under the Apache 2.0 license: Hugging Face.
Official announcement: blog.google.
Why it matters
AnalysisEmbeddingGemma 2 simplifies multimodal retrieval and matching while remaining compact and open for local deployment.
Discuss in community
Share your questions and insights with developers
Related in Ecosystem
Practical guides, core terminology, and agent skills
Gemini Flash & Pro (Google Gemini)
A family of multimodal models from Google DeepMind that combines a record context window (up to 2 million tokens), extreme generation speed (over 150 tokens/sec), and native perception of video and audio.
Google AI Studio: Free Gemini API Keys
Official Google sandbox: get free Gemini 2.0/1.5 API keys without a credit card, setup system prompts, and test the 2M token context window. Limits & guide 2026.
Google unveils Gemini 4 Neon: model outperforms Claude Opus 5.5 and GPT-6.2 Sol on coding and agentic tasks
Google has introduced Gemini 4 Neon, a new AI model that reportedly beats Claude Opus 5.5 and GPT-6.2 Sol on most tests, especially in programming, reasoning, and agent workflows.
Jev and System One AI: A Complete Practical Guide to the Decision Model from TypeSafe
A deep engineering breakdown of the flagship Jev model: System One architecture versus LLMs, Choice/Score/Noul primitives, request parallelism, confidence mathematics, video use cases, code, and an overview of local open-weight alternatives (Laya, GLiNER2.5, CLM-8B).