Google Introduces SKILL.state Architecture to Save Tokens in Agent Sessions
Researchers at Google have developed a new architecture, SKILL.state, which significantly reduces token consumption during agent operations.
Google Introduces SKILL.state Architecture to Save Tokens in Agent Sessions
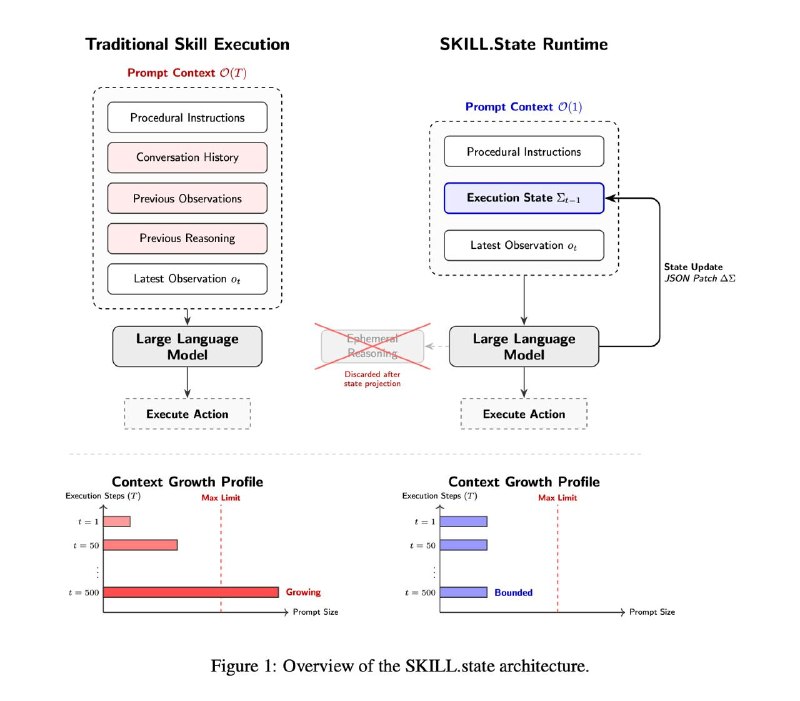
The authors propose the SKILL.state architecture: instead of accumulating dialogue history, it uses an explicit, mutable structured execution state.
Typically, agents operate on a ReAct-style principle, meaning that at each step, the entire accumulated dialogue is fed back into the model. This causes the prompt to grow linearly each time, while the total token consumption for the entire run grows quadratically. Additionally, the model is forced to extract the current task state from a mountain of text each time, which can sometimes provoke hallucinations.
The article suggests instead sending the model an explicit mutable structured execution state (referred to as execution state in the article) at each step. Here’s how it works:
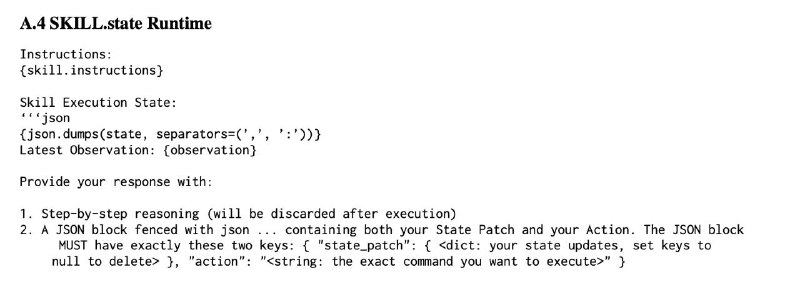
– At each step, the model, in addition to reasoning, outputs a JSON block with two fields: (1) a specific command that the agent must execute in the environment; (2) state_patch – information about what has changed relative to the previous state.
– The agent executes the command and receives a response from the environment, and the current state is updated according to the state_patch.
– For the next step, the updated state, system prompt, and the last response from the environment are passed. No previous messages, model reasoning from past steps, or anything else.
Thus, the prompt size at each step becomes constant, and the total token costs grow linearly.
In a synthetic warehouse management benchmark, SKILL.state saves 93.8% of tokens at 100 steps, and 98% at 200 steps. The longer the context, the more dramatic the gap.
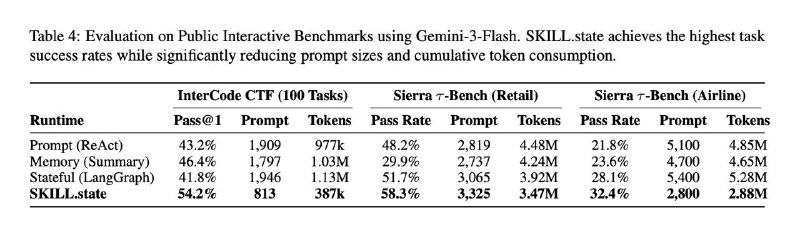
In real benchmarks, the savings are slightly lower, but SKILL.state sometimes even wins in accuracy. For example, on the InterCode CTF, it achieves 54.2% compared to 40-45% for baselines. This is due to the fact that representing the task through state results in a cleaner and less cluttered view free from distracting facts and incorrect hypotheses from past contexts.
This solution can be applied to any model, even closed ones, simply by changing the runtime. Appendix A provides the necessary prompt template, so it can be taken and used.
Why it matters
AnalysisThis new architecture significantly reduces token costs, which is critical for the efficiency of agent operations. It may also enhance the accuracy of task execution.
Discuss in community
Share your questions and insights with developers
Related in Ecosystem
Practical guides, core terminology, and agent skills
Loop Engineering: Architecture of Autonomous Agentic Loops and the Post-Prompting Era
A deep dive into Loop Engineering: self-sustaining execution loops for Claude Code and autonomous agents, the DOER/CHECKER topology, deterministic verification, the /goal primitive, and reward hacking mitigation.
Autonomous AI Operator on Telegram 24/7: Architecture, Telethon, Security, and 10 Production Scenarios
A comprehensive engineering guide to building a production-ready AI operator on Telegram using Telethon: session isolation, confirmation systems, ban protection, and 24/7 deployment.
Short-Term and Long-Term Memory of Agents
The architecture of multi-tier memory for autonomous agents. It distinguishes between Short-Term Memory (active context window of the current session) and Long-Term Memory (vector databases, user profile files, and episodic diaries).
Gemini Flash & Pro (Google Gemini)
A family of multimodal models from Google DeepMind that combines a record context window (up to 2 million tokens), extreme generation speed (over 150 tokens/sec), and native perception of video and audio.