Alibaba Unveils Qwen3.8-Flash-Next with Open Weights
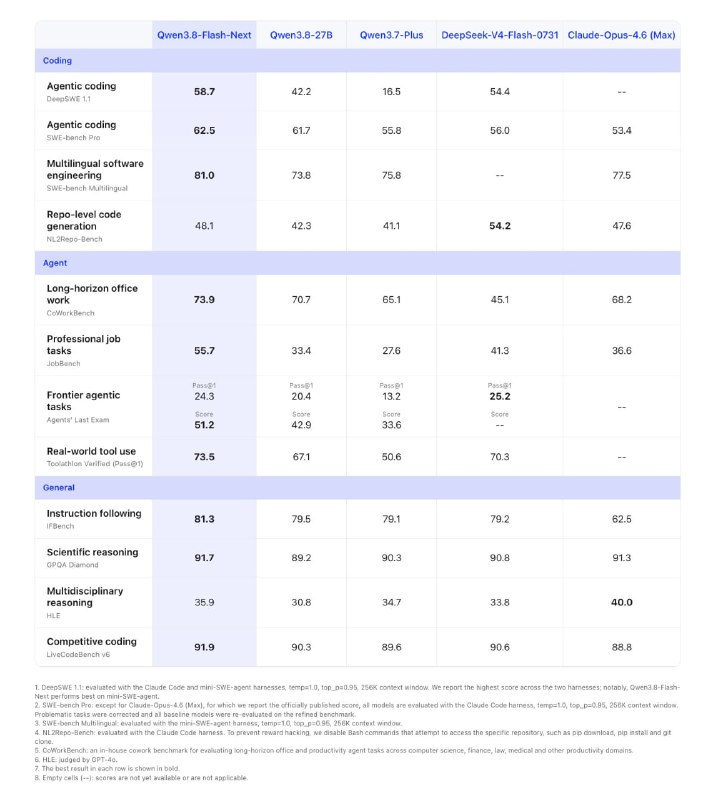
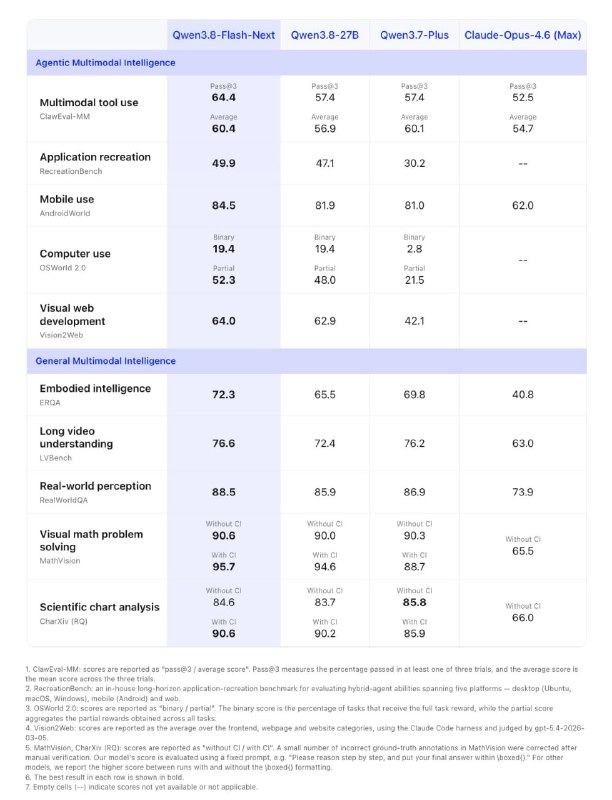
Alibaba has introduced the new Qwen3.8-Flash-Next model, which shows impressive results in tests, surpassing Claude Opus 4.6 Max.
Alibaba has unveiled Qwen3.8-Flash-Next with open weights, and it is already outperforming Claude Opus 4.6 Max in several tests.
This is not yet a full Qwen4, but an early preview of its architecture.
The model features 125 billion parameters for the main model plus 51 billion parameters for n-gram representations, with only 6 billion parameters activated per token.
Training costs were approximately 9 times cheaper than Qwen3.7-Plus, yet the model proved stronger in programming and office tasks.
Key results:
- SWE-bench Pro — 62.5 vs. 53.4 for Claude Opus 4.6 Max
- SWE-bench Multilingual — 81.0
- CoWorkBench — 73.9
- JobBench — 55.7
- Toolathlon — 73.5
- LiveCodeBench — 91.9
- GPQA Diamond — 91.7
- IFBench — 81.3
The native context is 256K tokens, expandable to 1 million through YaRN.
With a context of 1 million tokens, preprocessing speeds up by 7.6 times, and generation by 4.9 times.
A total of 6 billion active parameters per token, with performance already comparable to Opus in agent tasks and programming.
The model will soon be available via API, priced at $0.16 per 1 million input tokens and $0.47 per 1 million output tokens.
Why it matters
AnalysisThis news is significant as the new Qwen3.8-Flash-Next model demonstrates substantial improvements over previous versions, which could impact the development of artificial intelligence technologies.
Discuss in community
Share your questions and insights with developers
Related in Ecosystem
Practical guides, core terminology, and agent skills
Four Resume Tips from OpenAI’s Head of Applied AI Development
Wulfie Bain, OpenAI’s head of applied AI development, shared four resume rules: keep it short, remove irrelevant details, highlight outcomes, and lead with the strongest achievements.
GPT Image Generative Models Prompting Guide
OpenAI's gpt-image generative models are designed to produce production-quality visuals and fully controllable creative workflows. They are suitable for both professional design ta...
Claude Sonnet 4.6 vs GPT-5.5 vs Gemini 3.1 Pro: 2026 model comparison
Every few weeks, a new model comes out, and every time the same questions arise: should I switch? what changed what to pay for?
Thinking Machines Releases Inkling 2 Small: a 594B MoE Model That Can Fine-Tune Other Models
Thinking Machines released Inkling 2 Small, a 594B-parameter MoE model that leads among open models in several benchmarks and demonstrated autonomous fine-tuning of Qwen3.5-4B.