A new benchmark has appeared
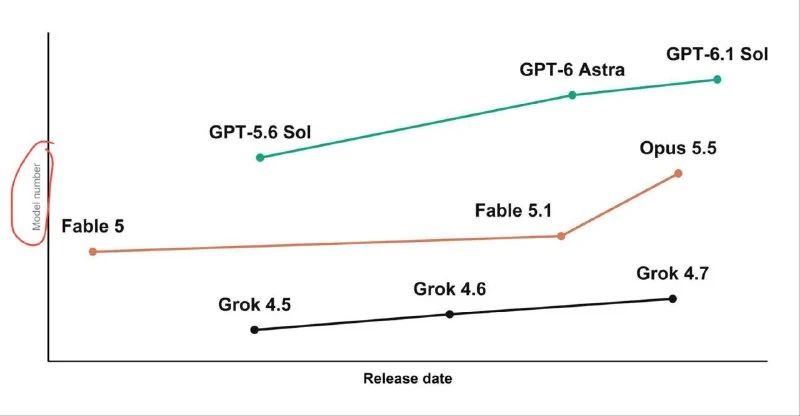
A new benchmark surfaced without disclosed details about the model or metrics.
A new benchmark has appeared without disclosed details.
The post contains no link to a repository, paper, model, or metrics, so its relevance and reliability cannot yet be assessed.
Why it matters
AnalysisBenchmarks help track AI progress, but without a source and metrics it is impossible to assess the quality of the test.
Discuss in community
Share your questions and insights with developers
Related in Ecosystem
Practical guides, core terminology, and agent skills
Claude Sonnet 4.6 vs GPT-5.5 vs Gemini 3.1 Pro: 2026 model comparison
Every few weeks, a new model comes out, and every time the same questions arise: should I switch? what changed what to pay for?
GPT-6.2 Astra: More 3D Generation Examples
GPT-6.2 Astra shows off 3D scenes, including recreations of Vice City and Rick Astley, while complex prompts can quickly consume subscription limits.
Agent Benchmarks: GAIA and SWE-bench
A new generation of rigorous practical benchmarks for evaluating the autonomy of artificial intelligence. GAIA tests multimodal tasks in the open web with files and a browser, while SWE-bench assesses agents' ability to find and fix real bugs in large GitHub repositories.
Agent Evals & SWE-bench Benchmarking
A methodology and infrastructure for systematically measuring the reliability, accuracy, and safety of AI agents through synthetic tests, SWE-bench, and headless repository simulations.