Sakana AI Proposes Brain-Inspired Alternative for Neural Network Training
Sakana AI introduces PC-ALM, a method combining predictive coding and Lagrange multipliers to train deep networks locally, mimicking biological learning processes.
Sakana AI Proposes Brain-Inspired Alternative for Neural Network Training
All modern neural networks we use are trained via backpropagation. This algorithm, invented in the 1970s, is still used everywhere.
However, there are several criticisms of it. The main issue lies in its structure. Backprop works strictly in three sequential phases: first, the signal passes forward through the network to produce an output; then, the error signal travels backward from the output to the input; and only then are the weights updated. Biologically, this is highly implausible: there is no mechanism that forces our neurons to wait for an error signal to arrive from somewhere through all other neurons before they can update.
Sakana AI is known for drawing inspiration from neuroscience. They propose looking towards an approach called predictive coding (a term from research on the visual cortex structure).
Usually, when we train a neural network, only its weights are optimized. In predictive coding, we optimize both the weights and the activations of each layer: each layer tries to predict the activity of the next layer, and only the residual that it couldn't explain is passed upwards. The idea is that the system must find a local equilibrium between the prediction error from below and from above, and then the network's outputs will accurately predict the target variable.
This approach wasn't invented by Sakana AI; it's quite well-known. But unfortunately, it didn't work: in deep networks, the signal simply attenuates, and nothing learns because the network doesn't know where to move the weights.
Sakana added just one small tweak — and the method started training networks up to 1000 layers effectively. The addition of a Lagrange multiplier (an old Soviet-era mathematical concept) helped. As early as 1988, Yann LeCun showed that if you formulate a neural network as a constrained optimization problem (as predictive coding does) and assign a Lagrange multiplier λ to each constraint, then at equilibrium, λ is exactly equal to the backprop gradient. This is a mathematical fact that Sakana decided to leverage.
In other words, while vanilla predictive coding provides an approximate signal, Sakana's approach — PC-ALM — converges exactly to the backprop gradient on linear networks using only connections with neighboring layers, without a single global pass.
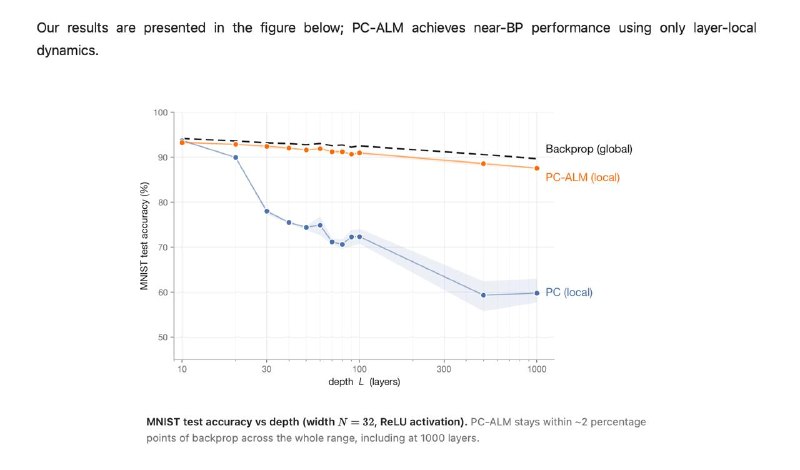
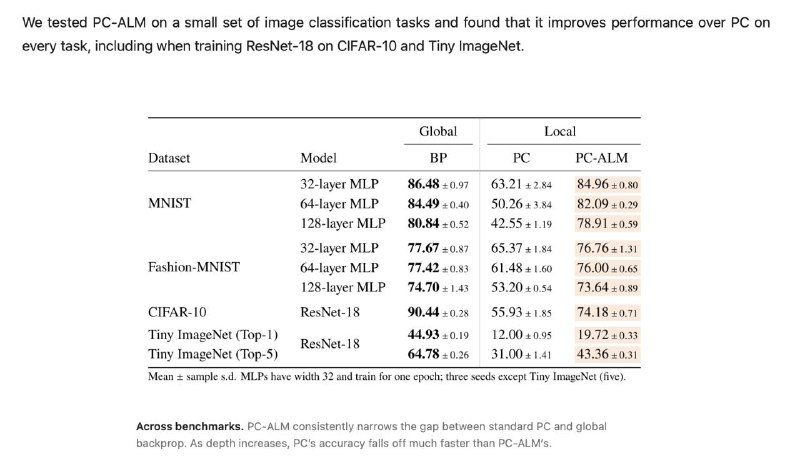
On various benchmarks, PC-ALM almost matches backprop (a difference of ~2 percentage points in accuracy on MNIST). And yes, there is no advantage in accuracy or training speed over backprop. It will likely win (eventually) only on neuromorphic hardware in the future. But we may have taken a step closer to recreating the learning process of a living brain. Plus, it's just elegant ☕️
Why it matters
AnalysisThis research bridges the gap between artificial neural networks and biological learning, potentially enabling more efficient, brain-like AI hardware.
Discuss in community
Share your questions and insights with developers
Related in Ecosystem
Practical guides, core terminology, and agent skills
Analog Anchoring for Engineers
A system of regular analog practices (paper notebooks, physical whiteboards, gadget-free walks, and manual labor) to alleviate synthetic overload and restore brain plasticity.
MIT researchers show LLMs can read and edit neural network weights without training
MIT CSAIL researchers introduced Weight-Space Programming, where an LLM directly reads and modifies model weights; Astra improved Qwen3.5-0.8B math scores without gradient descent or fine-tuning.
Weights and Biases of Neural Networks
The fundamental nature of a trained neural network. Weights are matrix coefficients representing the strength of connections between artificial neurons, while biases are the activation sensitivity thresholds. This entry explains storage formats (.safetensors, bfloat16, fp8) and weight inspection via Python and CLI.
7 Best Cheap Alternatives to Claude Code: Pick the Right Tool
Claude Code has become a leading name in agentic coding. Discover the 7 best CLI alternatives: OpenCode, Pi, Factory Droid, Codex CLI, Antigravity CLI, Cline, and Goose.