DeepSeek Releases New Multimodal Model for Agents
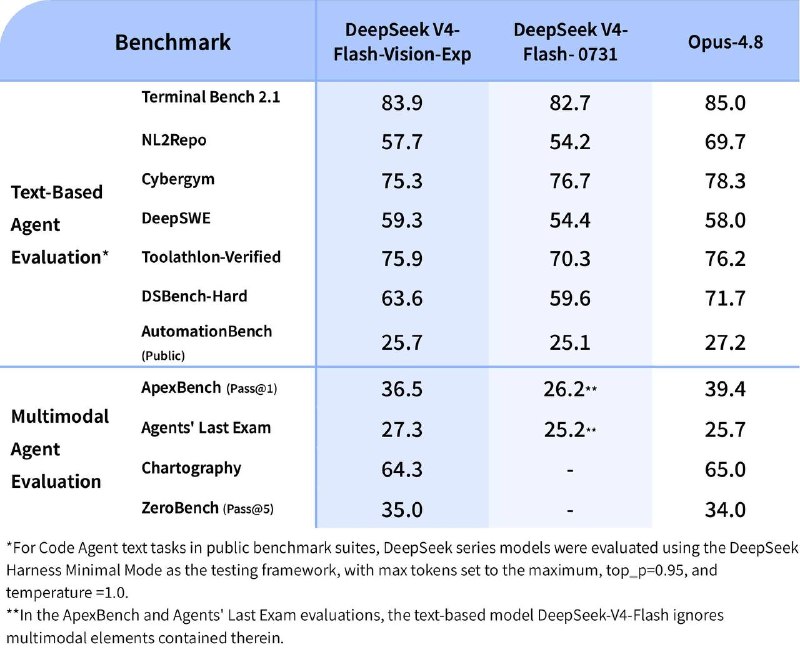
DeepSeek has introduced a new multimodal model, DeepSeek-V4-Flash-Vision-Exp, which showcases high performance in agent scenarios. The model maintains productivity levels of previous versions and a new version of DeepSeek Harness has also been released.
DeepSeek Releases New Multimodal Model for Agents
DeepSeek has unveiled a new multimodal model called DeepSeek-V4-Flash-Vision-Exp. This model is an extension of V4-Flash, specifically designed for multimodal agent scenarios.
Despite the "Flash" in its name, the model performs at a level comparable to Opus 4.8, and in some cases, even better. At the same time, its text processing capabilities remain on par with the official DeepSeek-V4-Flash.
Additionally, a new version, DeepSeek Harness 0.1.1, has been released, providing out-of-the-box support for the model.
Pricing for DeepSeek-V4-Flash is up to 384 tokens per image, and it supports JPEG, PNG, GIF, and WebP formats.
Why it matters
AnalysisThis new model from DeepSeek opens up new possibilities for agent scenarios, potentially enhancing the efficiency of working with multimodal data. It also maintains high performance in text tasks, making it a versatile tool for developers.
Discuss in community
Share your questions and insights with developers
Related in Ecosystem
Practical guides, core terminology, and agent skills
GPT Image Generative Models Prompting Guide
OpenAI's gpt-image generative models are designed to produce production-quality visuals and fully controllable creative workflows. They are suitable for both professional design ta...
Claude Sonnet 4.6 vs GPT-5.5 vs Gemini 3.1 Pro: 2026 model comparison
Every few weeks, a new model comes out, and every time the same questions arise: should I switch? what changed what to pay for?
DeepSeek (Chinese Breakthrough in Open AI)
A series of groundbreaking open models from the Chinese lab DeepSeek (V3, R1). Demonstrates top-tier coding and reasoning capabilities at a cost 10–20 times lower than Western commercial counterparts.
Google Gemini Pro (Model with Infinite Context)
The flagship working model from Google DeepMind featuring a record context window of over 2 million tokens. Capable of analyzing entire books, lengthy videos, and massive codebases in a single query.