DeepSeek wprowadza nowy model multimodalny dla agentów AI
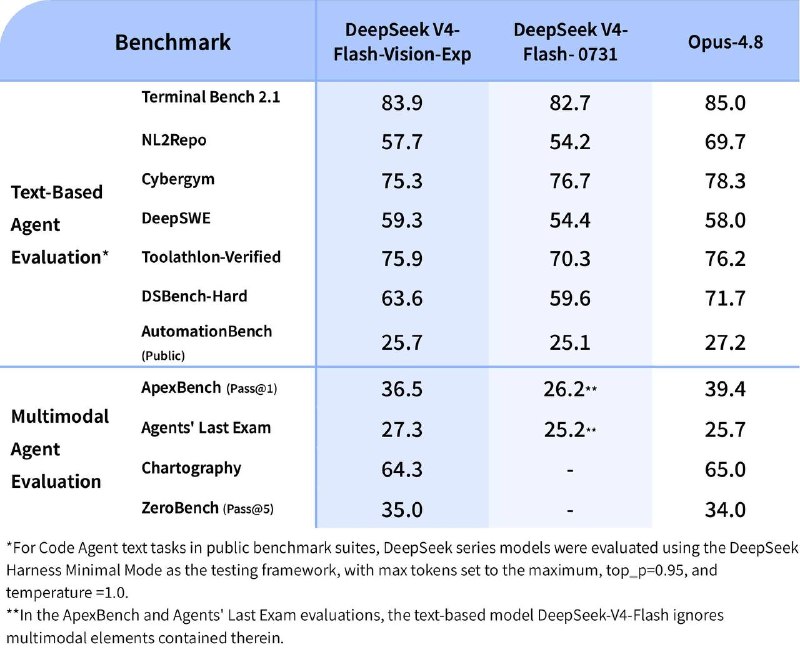
DeepSeek zaprezentował DeepSeek-V4-Flash-Vision-Exp, zaawansowany model multimodalny o wydajności porównywalnej z Opus 4.8, dedykowany do scenariuszy agentowych.
DeepSeek Releases New Multimodal Model for Agents
DeepSeek unveiled a new multimodal model called DeepSeek-V4-Flash-Vision-Exp. This model is an extension of V4-Flash, specifically designed for multimodal agent scenarios.
Despite the "Flash" in its name, the model performs at a level comparable to Opus 4.8, and in some cases, even better. At the same time, its text processing capabilities remain on par with the official DeepSeek-V4-Flash.
Additionally, a new version, DeepSeek Harness 0.1.1, has been released, providing out-of-the-box support for the model.
Pricing for DeepSeek-V4-Flash is up to 384 tokens per image, and it supports JPEG, PNG, GIF, and WebP formats.
Dlaczego to ważne
AnalizaNowy model otwiera możliwości w zakresie automatyzacji zadań wielomodalnych, zachowując jednocześnie wysoką efektywność w przetwarzaniu tekstu. Stanowi wszechstronne narzędzie dla deweloperów budujących zaawansowane systemy agentowe.
Dyskutuj w społeczności
Dziel się swoimi pytaniami i spostrzeżeniami z programistami