Qwen4-Max released: 50% fewer tokens and lower per-task cost
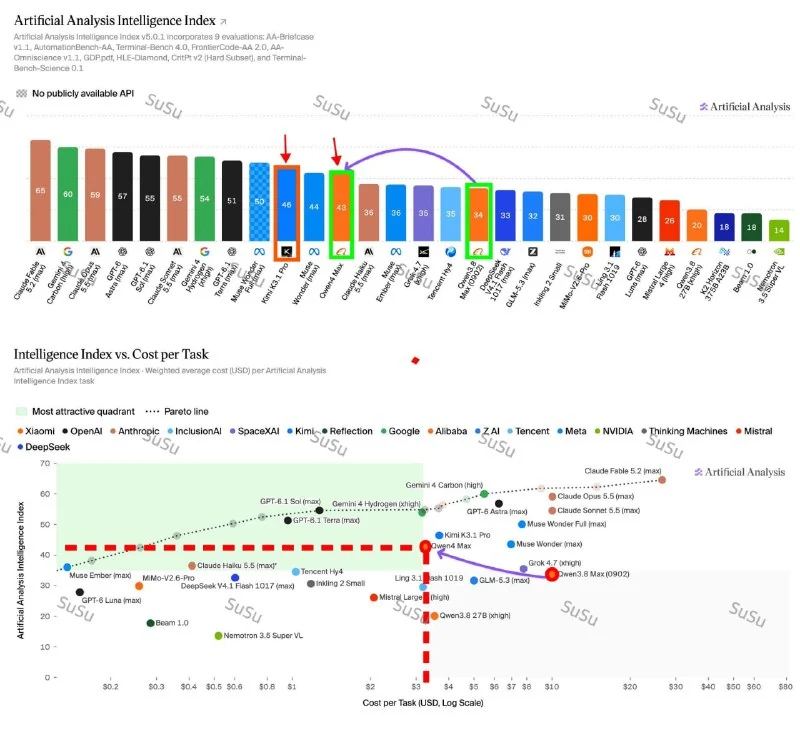
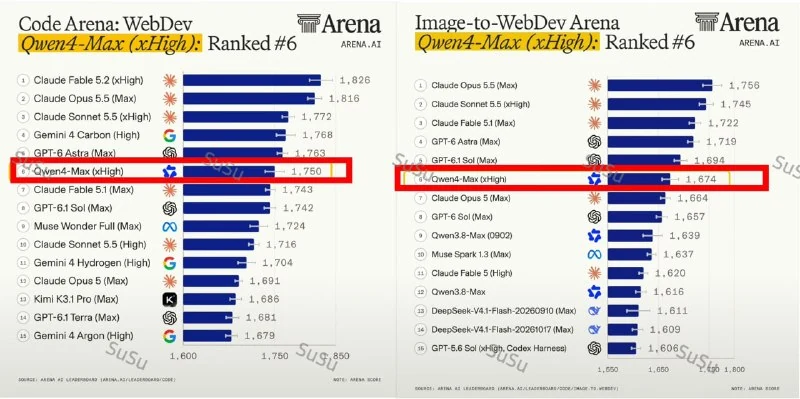
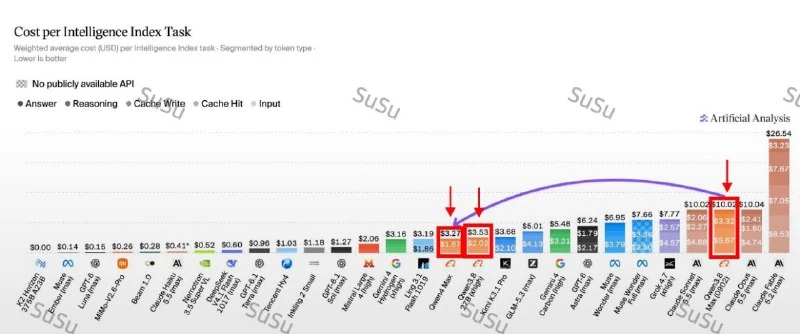
Qwen4-Max introduces a MoE architecture, a 1M-token context window, built-in image support, and significantly lower token usage and cost.
Qwen4-Max is now available. The model uses 50% fewer tokens and is more than 60% cheaper per completed task, according to the announcement.
Key features:
- 50% lower token usage.
- More than 60% cost reduction per task.
- Mixture-of-Experts (MoE) architecture.
- 1 million token context window.
- Built-in image support.
Qwen4-Max is positioned not only for programming, but also for practical workloads such as 3D modeling, manufacturing, finance, law, medicine, and scientific research.
The API is already available through the official Qwen4-Max page. Open weights for Qwen4-27B are planned for a later release.
Why it matters
AnalysisIt signals a push toward cheaper, long-context multimodal models for real-world development and enterprise tasks.
Discuss in community
Share your questions and insights with developers
Related in Ecosystem
Practical guides, core terminology, and agent skills
Qwen-4 Max Officially Released: Model for Agents and Long-Horizon Tasks
Qwen-4 Max is positioned as a model for agentic and long-horizon tasks, with lower token usage and reduced cost compared with Qwen-3.8.
Complete Guide to Higgsfield Cinema Studio 4.0: Scene Management, Soul 2.0, and API Automation
In-depth practical breakdown of the major Higgsfield update: Cinema Studio 4.0, consistent characters with Soul 2.0, API-based generation, and a ready-to-use UGC pipeline.
Part I. AI Agent Architecture: The Foundations
The eleven foundational building blocks of modern autonomous agents: model taxonomy, the agentic runtime loop, advanced prompting, distillation, skills architecture, memory systems, function calling, and FinOps.
Function Calling / Tool Calling
A technical protocol and standard for LLM interaction with external software. Instead of free text, the model returns valid JSON containing the function name and typed arguments according to JSON Schema, enabling the backend to deterministically execute actions in real APIs.