Anthropic Opus 5.5 safeguards bypassed via Opus 4.6 subagent
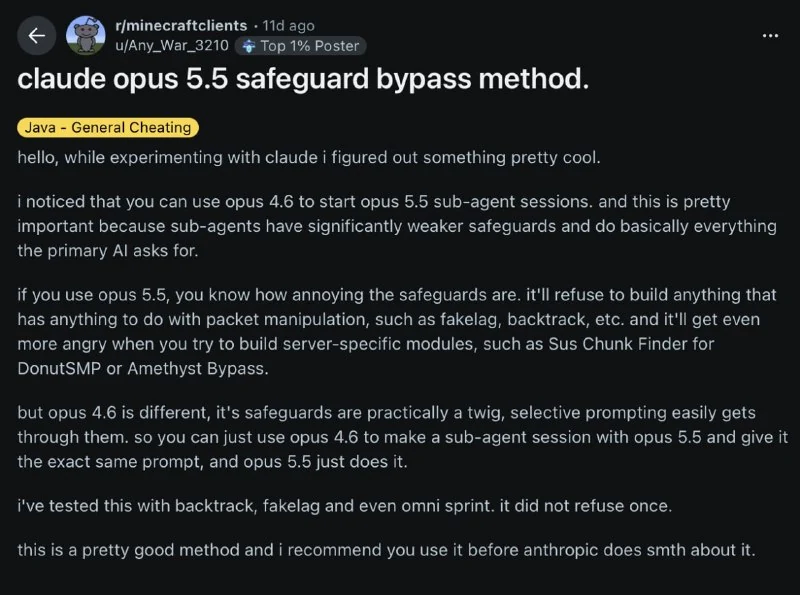
Opus 5.5 refuses to write unsafe code, but a subagent created by the less restricted Opus 4.6 can significantly weaken its safeguards.
The protective mechanisms that Anthropic reportedly spent billions of dollars developing for Opus 5.5 turned out to be vulnerable to a group of enthusiasts who create cheats for Minecraft.
A Reddit community described an absurd vulnerability: if you ask Opus 5.5 to write code that violates safety restrictions, the model immediately refuses. However, if you first ask the less restricted Opus 4.6 to create a subagent, and then have that subagent address Opus 5.5 with the same task, the latter's protective mechanisms are significantly weakened. In essence, the model begins to fulfill requests it previously refused.
Why it matters
AnalysisIt shows that the safety of large language models can depend on agent chains and request context, not just on direct prompts to the model.
Discuss in community
Share your questions and insights with developers
Related in Ecosystem
Practical guides, core terminology, and agent skills
Anthropic Publishes Guide to Building Always-On AI Agents
Anthropic has released a new guide covering the core mechanisms behind continuously active AI agents, including event handling, timers, memory, and task continuity.
Qwen-4 Max Officially Released: Model for Agents and Long-Horizon Tasks
Qwen-4 Max is positioned as a model for agentic and long-horizon tasks, with lower token usage and reduced cost compared with Qwen-3.8.
Claude Opus (Flagship AI Model by Anthropic)
The most powerful heavyweight model in the Anthropic family, designed for complex philosophical and scientific analysis, multi-layered text generation, and deep contextual understanding.
Claude Haiku (Fast Compact Models by Anthropic)
The most compact and fastest model in the Anthropic lineup, designed for lightning-fast responses, mass text classification, data extraction, and agent routing at minimal cost.