OpenAI fixes Codex usage-limit error and will compensate users with credits
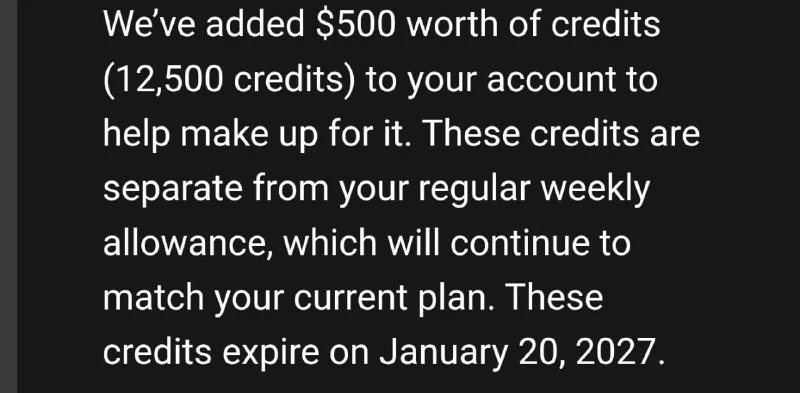
OpenAI said about 40,000 Codex accounts had incorrectly set usage limits, causing credits to be consumed faster than expected. The company fixed the issue and will give affected users free credits worth $500 to $1,000.
OpenAI said that roughly 40,000 Codex accounts had incorrectly configured usage limits, causing credits to be consumed faster than expected.
The issue has already been fixed, and affected users will receive compensation in the form of free credits worth $500 to $1,000.
One user reported receiving more than 12,000 credits.
If you use Codex, check Settings → Usage & billing → Credits or your email for updates.
Why it matters
AnalysisBilling and usage-limit mistakes in AI coding tools can directly affect developers' costs and trust in paid services. Checking credit balances and official notifications is now a practical step for Codex users.
Discuss in community
Share your questions and insights with developers
Related in Ecosystem
Practical guides, core terminology, and agent skills
OpenAI expands caching in Codex, Work and API
OpenAI made caching persistent in Codex and Work and added a 12-hour cache retention option in the API at twice the cost of 30-minute caching.
Codex Skills for Beginners: Automating AI Agent Workflows
A comprehensive hands-on guide to building and executing Codex Skills: SKILL.md anatomy, explicit vs. auto-triggering, skills vs. scripts vs. tools, Skills API, and safety boundaries.
Part II. How to Work with Codex + Optimization/Security/Team
Codex is not just code autocomplete in a chat; it is a full-fledged engineering agent: it reads the repository, plans changes, edits files, runs tests, reviews its own diffs, and c...
OpenAI GPT (Flagship Models of the GPT Series)
The primary universal line of large language models from OpenAI (GPT-4, GPT-4o). Optimized for complex text analysis, programming, creativity, and daily intellectual tasks.
OpenAI extends prompt caching in API to 12 hours
OpenAI has expanded prompt caching in its API: caches can now persist for up to 12 hours, and indefinitely for authorized Codex and Work users.
GPT Mini (Compact Models of the GPT-4o Mini Series)
An economical and ultra-fast version of OpenAI's flagship models. Optimized for mass daily tasks, instant responses, text classification, and limit conservation.