MiniMax releases M3.1 Flash model
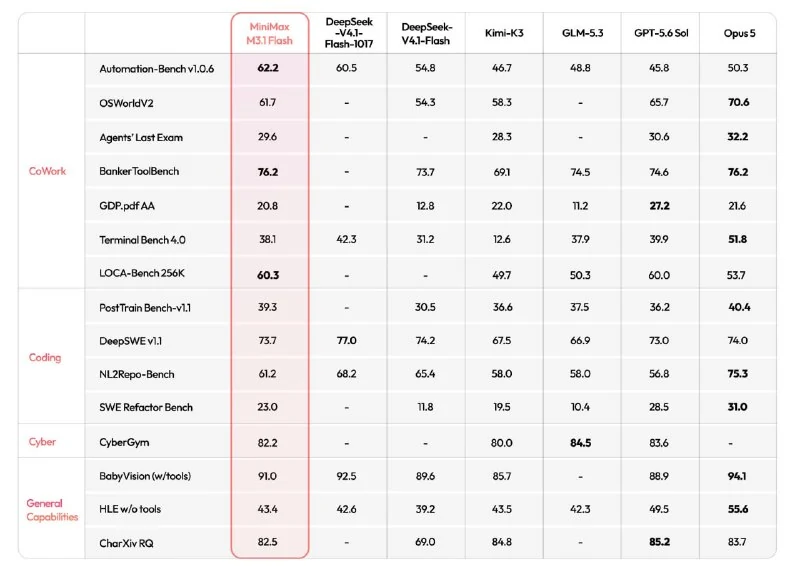
MiniMax has officially released M3.1 Flash, a model that generates over 200 tokens per second, outperforms several Chinese models on AI-agent benchmarks, and is significantly cheaper than M3.
MiniMax M3.1 Flash officially released
Space Bunny was an early version of this model, and the team has now introduced it as M3.1 Flash. The specifications look promising.
- More than 200 tokens per second.
- Outperforms other Chinese models in AI-agent benchmarks.
- API pricing is approximately $0.15 per million input tokens and $0.60 per million output tokens.
- Model weights will be published on October 23.
- A Pro version is also in preparation.
This is a major step forward compared with M3: the new model is nearly 3 times faster and 70% cheaper.
The model is already available through the API and MiniMax pricing plans. Until October 25, it can be used for free under these plans.
It can also be tested for free in OpenCode for the next three days.
Why it matters
AnalysisM3.1 Flash combines high throughput, lower cost, and upcoming open weights, making it relevant for developers building AI agents and other LLM applications.
Discuss in community
Share your questions and insights with developers