DeepSeek wprowadza nowy model multimodalny dla agentów AI
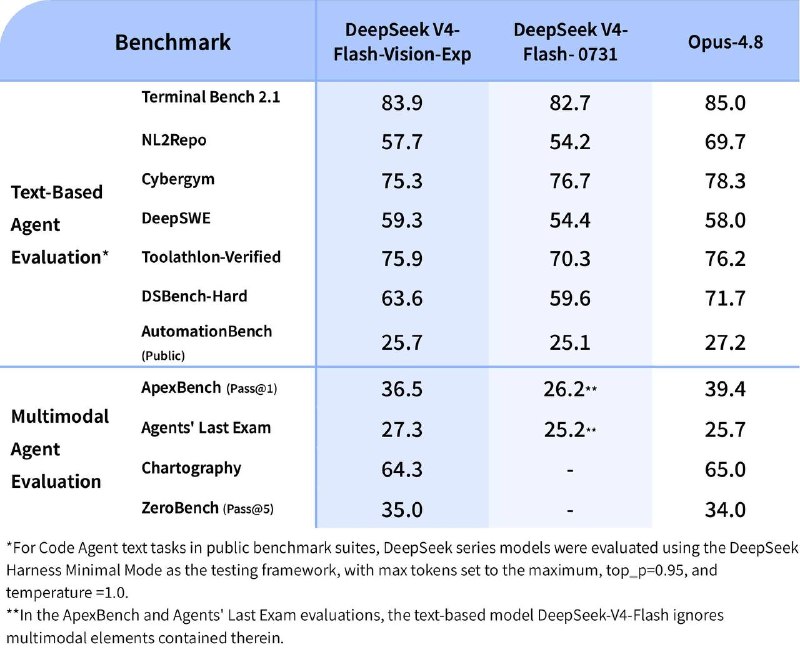
DeepSeek zaprezentował DeepSeek-V4-Flash-Vision-Exp, zaawansowany model multimodalny o wydajności porównywalnej z Opus 4.8, dedykowany do scenariuszy agentowych.
DeepSeek Releases New Multimodal Model for Agents
DeepSeek unveiled a new multimodal model called DeepSeek-V4-Flash-Vision-Exp. This model is an extension of V4-Flash, specifically designed for multimodal agent scenarios.
Despite the "Flash" in its name, the model performs at a level comparable to Opus 4.8, and in some cases, even better. At the same time, its text processing capabilities remain on par with the official DeepSeek-V4-Flash.
Additionally, a new version, DeepSeek Harness 0.1.1, has been released, providing out-of-the-box support for the model.
Pricing for DeepSeek-V4-Flash is up to 384 tokens per image, and it supports JPEG, PNG, GIF, and WebP formats.
Dlaczego to ważne
AnalizaNowy model otwiera możliwości w zakresie automatyzacji zadań wielomodalnych, zachowując jednocześnie wysoką efektywność w przetwarzaniu tekstu. Stanowi wszechstronne narzędzie dla deweloperów budujących zaawansowane systemy agentowe.
Dyskutuj w społeczności
Dziel się swoimi pytaniami i spostrzeżeniami z programistami
Powiązane w ekosystemie
Praktyczne poradniki, kluczowa terminologia i skille agentów
DeepSeek Harness wprowadza Creator Mode do tworzenia własnych pluginów
DeepSeek Harness dodał tryb Creator Mode, który pozwala tworzyć własne pluginy, przestrzenie robocze, narzędzia i interfejsy. Deweloperzy opublikowali również prompty w językach angielskim i chińskim, użyte do stworzenia demonstracyjnych pluginów.
Przewodnik po promptach dla modeli generatywnych GPT Image
Modele generowania obrazów gpt-image od OpenAI zostały zaprojektowane w celu tworzenia wizualizacji o jakości produkcyjnej oraz umożliwienia pełnej kontroli nad procesami twórczymi. Są one odpowiednie zarówno dla profesjonalnych projektantów...
Claude Sonnet 4.6 vs GPT-5.5 vs Gemini 3.1 Pro: porównanie modeli na rok 2026
Co kilka tygodni pojawia się nowy model, a za każdym razem padają te same pytania: czy warto przejść? Co się zmieniło? Za co płacić?
DeepSeek (Chiński przełom w otwartym AI)
Seria przełomowych modeli open-source od chińskiego laboratorium DeepSeek (V3, R1). Prezentuje najwyższy poziom w kodowaniu i rozumowaniu przy kosztach 10–20 razy niższych niż zachodnie odpowiedniki komercyjne.