Andrej Karpathy's Tips for Working with LLMs
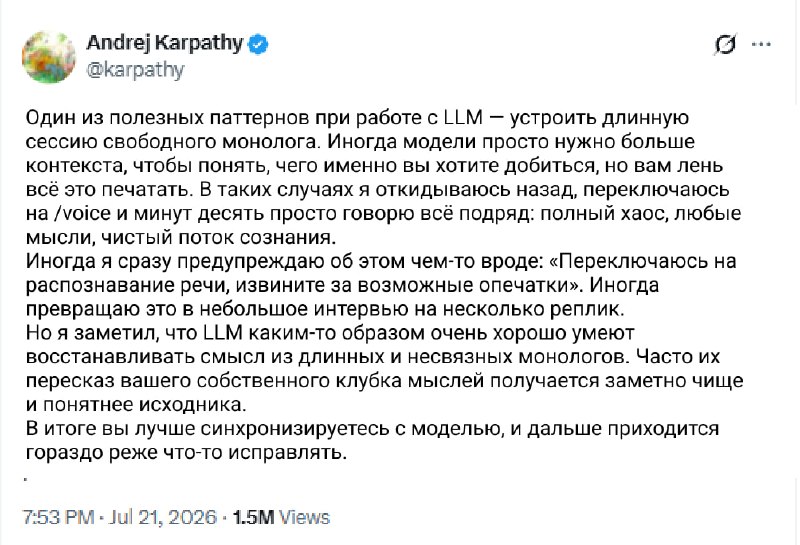
Andrej Karpathy shares his favorite methods for working with LLMs, suggesting the use of voice mode to create chaotic monologues.
Andrej Karpathy's Tips for Working with LLMs
Andrej Karpathy talked about one of his favorite ways to work with LLMs. He advises sometimes not to try to formulate the perfect prompt, but rather to simply dictate a long stream of thoughts to the model.
You can turn on voice mode and talk for about ten minutes about anything: with repetitions, mistakes, fragments of phrases, and jumps between topics. According to him, LLMs are good at assembling such chaotic monologues into a coherent picture and often articulate your thoughts much more clearly than you do.
Sometimes, this session can be turned into a small interview with several exchanges. As a result, the model better understands the context and the ultimate goal, and you find yourself needing to correct it much less often.
Why it matters
AnalysisThis approach allows for more effective use of LLMs, simplifying the prompt formulation process and improving outcomes.
Discuss in community
Share your questions and insights with developers
Related in Ecosystem
Practical guides, core terminology, and agent skills
AI Radar: GPT-6.1 Terra, Gemini 4 Carbon, Mistral Large 4 and OpenAI/Anthropic pricing changes
A roundup of recent AI news: new LLM releases, OpenAI and Anthropic subscription changes, world models, video generation, and research updates.
MIT researchers show GPT-6 Astra can improve other AI models by editing their weights
In an experiment, Astra raised Qwen3.5-0.8B's accuracy on MATH-500 from 7.9% to 48.1% by changing only 0.016% of the model's weights.
Part I. AI Agent Architecture: The Foundations
The eleven foundational building blocks of modern autonomous agents: model taxonomy, the agentic runtime loop, advanced prompting, distillation, skills architecture, memory systems, function calling, and FinOps.
Part II. AI Agent Architecture: From Model to Memory and Tools
A deep engineering dive: tokenization, KV-cache, sampling determinism, the training stack, quantization, context engineering, the safety stack, production RAG, ReAct, and multi-agent swarm systems.