Thinking Machines Releases Looped Transformer Inkling 2 Mini
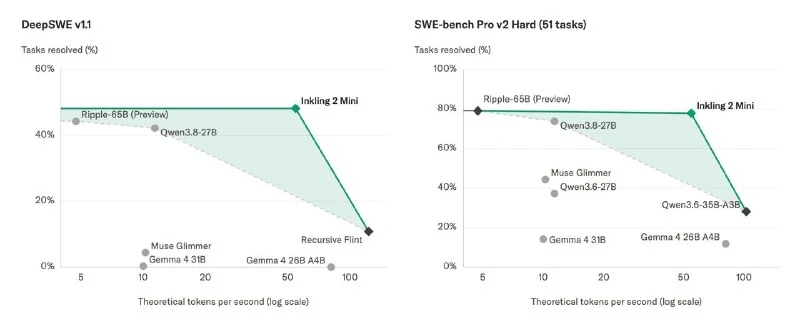
Thinking Machines, the startup founded by Mira Murati, has released Inkling 2 Mini, a model based on the looped transformer architecture. This is the same approach that, according to speculation, may underlie GPT-6 Astra.
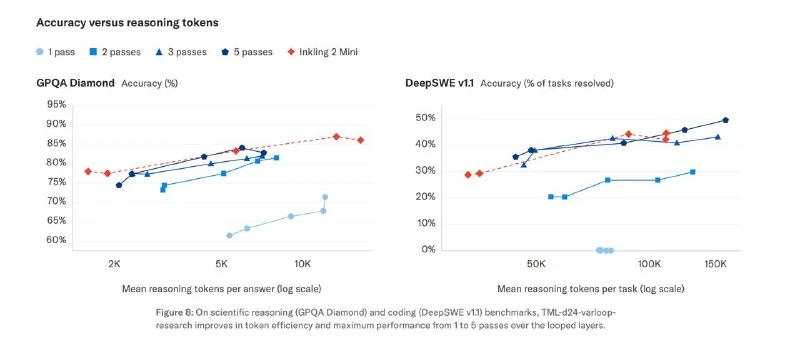
The core idea is simple: instead of running a fixed stack of different layers exactly once, the model passes the hidden state through the same block of layers multiple times before generating the next token. This adds reasoning depth without increasing the number of parameters or spending extra tokens on reasoning.
Many assume that this architecture may also have influenced Fable 5.2 and GPT Sol. Looping layers could help explain the recent drop in model costs and improved token efficiency observed in the past few months.
Thinking Machines released a compact looped transformer designed for local inference:
- 26.4B total parameters;
- approximately 3.4B active parameters;
- about 5.4B weight activations per token thanks to repeated layer passes.
The model has 24 layers organized into four blocks of six. The first and last blocks run once, while the two middle blocks run three times each. As a result, each token requires 48 layer applications. Only the middle layers are repeated because, according to the authors, they perform more abstract reasoning. In tests, this produced significantly better results than looping the final 12 layers.
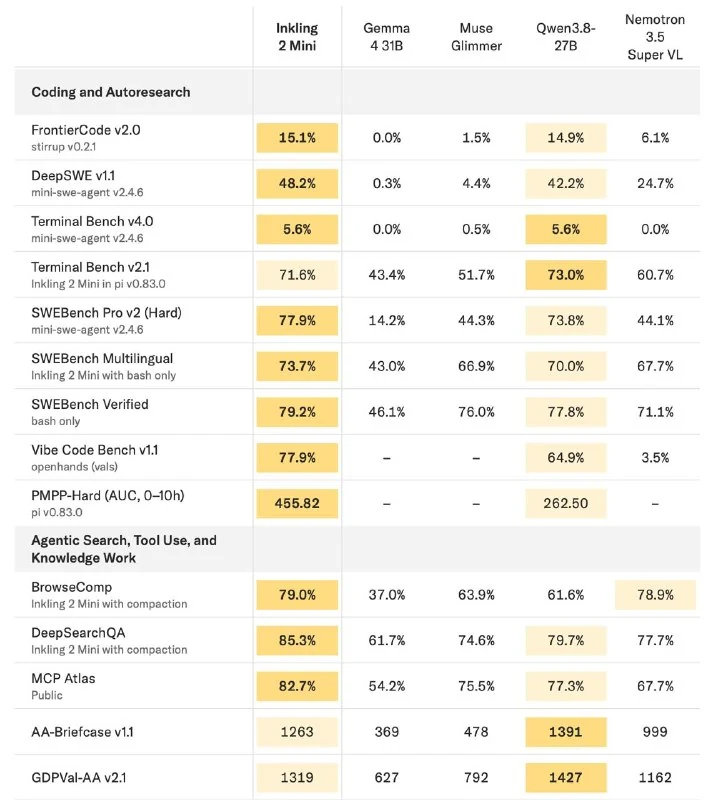
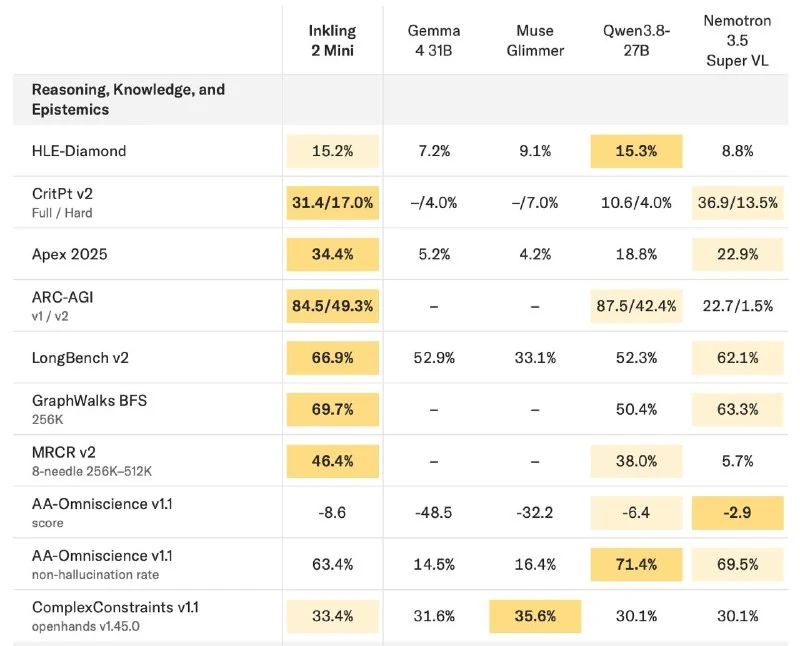
On benchmarks, the model performs at a level comparable to Qwen3.8-27B, and even higher on some metrics, despite having fewer parameters. For local deployment, it is a genuinely interesting option.
Why it matters
AnalysisInkling 2 Mini shows that looped transformers can increase reasoning depth without proportionally increasing model size. This matters for local and edge AI, where memory and compute budgets are limited.
Discuss in community
Share your questions and insights with developers
Related in Ecosystem
Practical guides, core terminology, and agent skills
Thinking Machines releases Inkling 2 Mini, an open-weights model for local coding
Thinking Machines has released Inkling 2 Mini, an open-weights transformer with a cyclic architecture that can run locally on a Mac and was used to build a flight simulator offline.
OpenAI Releases GPT 6.2 Astra and Sol
OpenAI has launched GPT 6.2 Astra and Sol, with Astra topping agent benchmarks and offering more competitive token pricing.
Part I. AI Agent Architecture: The Foundations
The eleven foundational building blocks of modern autonomous agents: model taxonomy, the agentic runtime loop, advanced prompting, distillation, skills architecture, memory systems, function calling, and FinOps.
Part II. AI Agent Architecture: From Model to Memory and Tools
A deep engineering dive: tokenization, KV-cache, sampling determinism, the training stack, quantization, context engineering, the safety stack, production RAG, ReAct, and multi-agent swarm systems.