NVIDIA Releases Personal AI Router
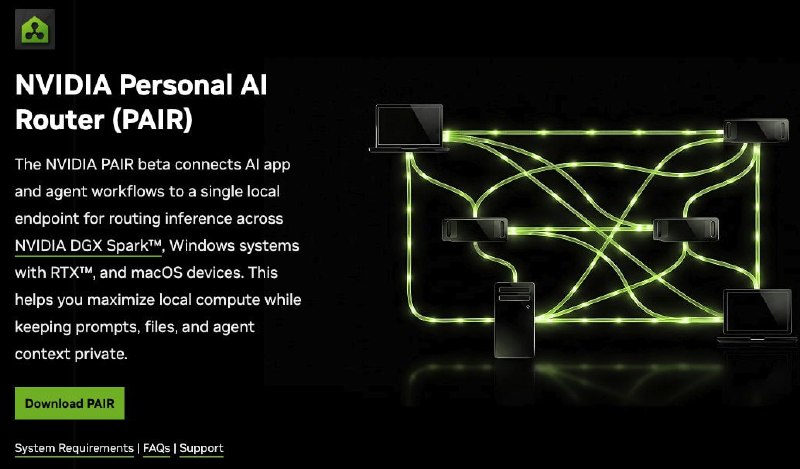
NVIDIA has introduced the Personal AI Router, enabling users to create a personal AI cluster from computers in their local network. This solution supports various operating systems and is available in beta for free.
NVIDIA Releases Personal AI Router
PAIR allows users to combine computers in a local network and turn them into a personal AI cluster.
It automatically finds PCs with RTX, DGX Spark, and supported Macs, sending requests to the machine with available resources. Essentially, it's a load balancer for AI agents right in your home.
Features
- Run multiple AI agents in parallel.
- Distribute inference across multiple GPUs and computers.
- Store prompts, files, and agent context only within your network.
Supported Platforms
- Windows
- Linux
- macOS
PAIR is already available in beta for free and open-source.
Why it matters
AnalysisThis product allows users to effectively utilize their computer resources for AI tasks, significantly enhancing productivity. The open-source nature also fosters community development and innovation in the field.
Discuss in community
Share your questions and insights with developers
Related in Ecosystem
Practical guides, core terminology, and agent skills
Nvidia's Monopoly and the CUDA Platform
An analysis of Nvidia's technological and economic dominance in the AI market. The CUDA (Compute Unified Device Architecture) platform, created in 2006, transformed ordinary gaming GPUs into the planet's primary computational tool, making it difficult for competitors like AMD and Intel to break this monopoly.
JSON — Structured Data for Programs, APIs, and AI Agents
A complete hands-on guide to JSON: syntax specifications, serialization via parse and stringify, REST API consumption, JSON Schema validation, and structured outputs for LLMs.
DOCX and XLSX Formats: When AI Needs to Deliver Production-Ready Documents
A comprehensive hands-on guide to generating and processing DOCX documents and XLSX workbooks with AI: comparing against Markdown and CSV, prompt engineering, formula design, and code automation.
TensorRT-LLM & SGLang High-Speed Engines
Deeply compiled computational engines for extreme optimization of language model inference on NVIDIA servers, utilizing graph optimization, FlashAttention-3, and advanced routing.