US Federal Register Uses Chinese Qwen Model for Document Search
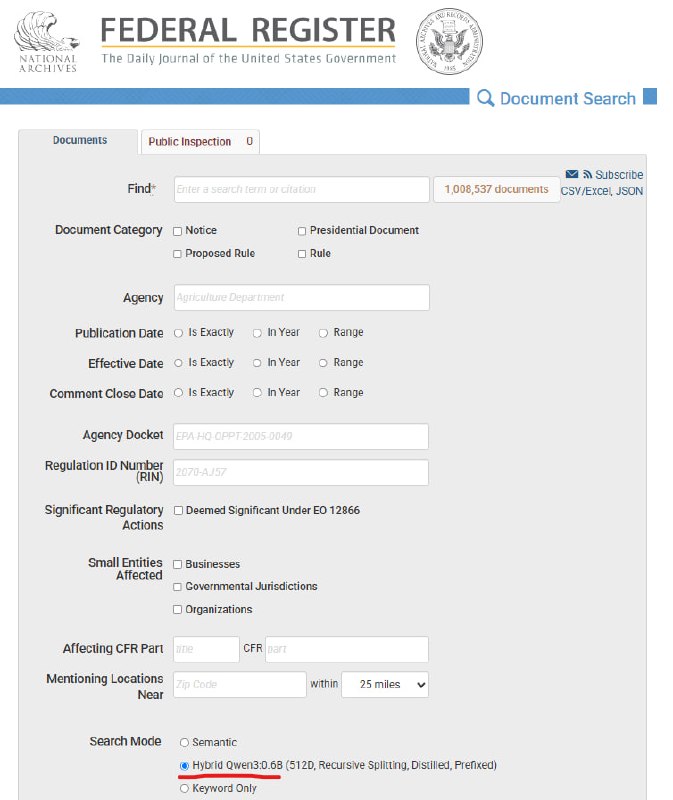
The US Federal Register utilizes a distilled version of the Chinese Qwen model to search through government documents, creating an ironic backdrop to accusations against China.
The US Federal Register is using a distilled version of the Chinese model Qwen to search through government documents.
The settings explicitly state Hybrid Qwen3:0.6B Distilled.
This looks particularly ironic against the backdrop of accusations against China for "industrial-scale model distillation."
Why it matters
AnalysisThis highlights the global reliance on Chinese open-source AI models and underscores the irony of geopolitical tensions regarding AI technology theft.
Discuss in community
Share your questions and insights with developers
Related in Ecosystem
Practical guides, core terminology, and agent skills
MIT researchers show GPT-6 Astra can improve other AI models by editing their weights
In an experiment, Astra raised Qwen3.5-0.8B's accuracy on MATH-500 from 7.9% to 48.1% by changing only 0.016% of the model's weights.
DOCX and XLSX Formats: When AI Needs to Deliver Production-Ready Documents
A comprehensive hands-on guide to generating and processing DOCX documents and XLSX workbooks with AI: comparing against Markdown and CSV, prompt engineering, formula design, and code automation.
Model Distillation & Reasoning Transfer
A methodology for transferring knowledge and reasoning chains from a large Teacher Model to a compact Student Model for fast and cost-effective inference.
MIT researchers show LLMs can read and edit neural network weights without training
MIT CSAIL researchers introduced Weight-Space Programming, where an LLM directly reads and modifies model weights; Astra improved Qwen3.5-0.8B math scores without gradient descent or fine-tuning.