Models296•07/23/2026, 09:15Quantization Methods for LLMs to Run a 70B Model on a Single GPU3 min readRead
Models308•07/15/2026, 09:30Startup PrismML Announces the Largest Model in the World for Smartphone Deployment2 min readRead
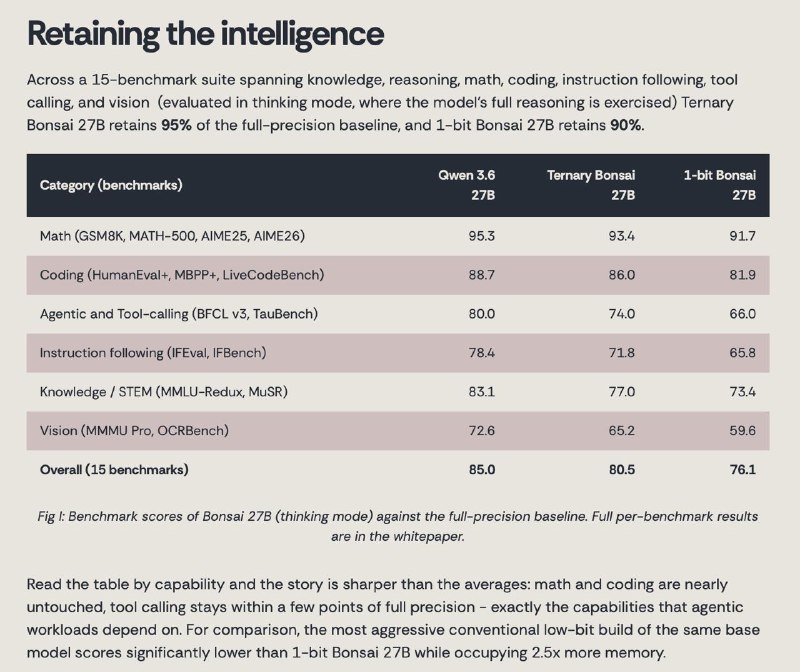
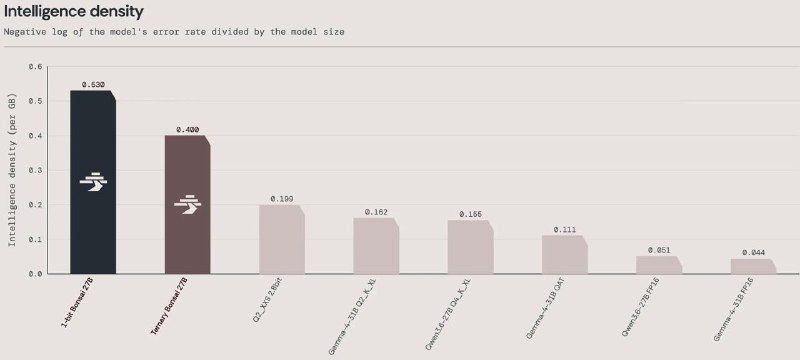
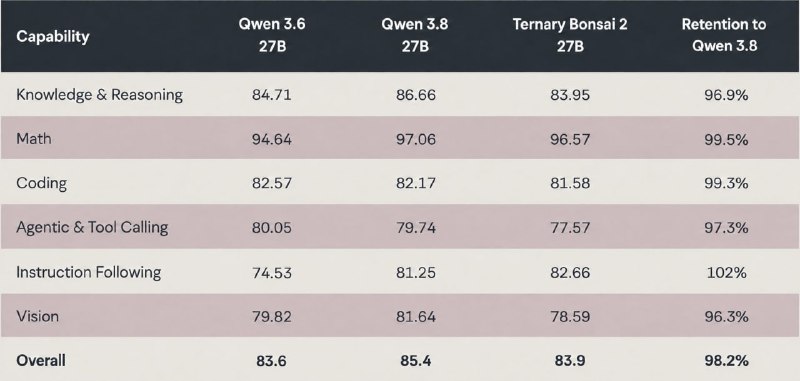
Models297•09/18/2026, 07:17PrismML Releases Bonsai 2 27B: A 5.9GB Local AI Model Based on Qwen2 min readRead
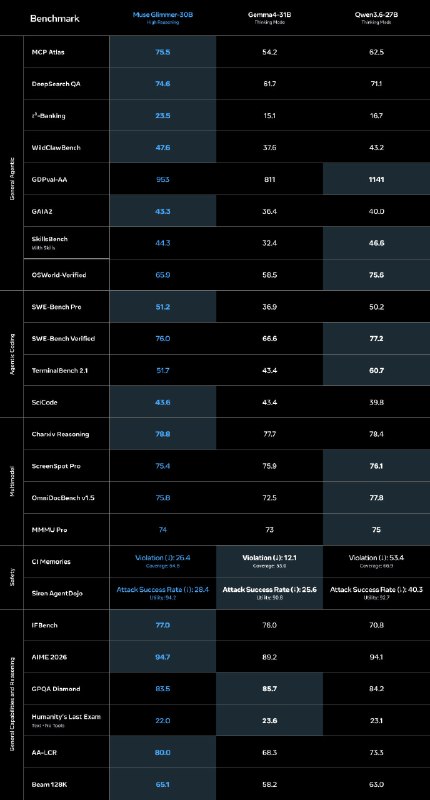
Models337•08/10/2026, 12:00Meta Releases Muse Glimmer and Promises to Open Weights for Muse Spark 1.22 min readRead
GitHub690•06/23/2026, 09:00Victor Musta, Product Lead at Hugging Face, recommends a detailed guide on optimizing local LLM deployment via llama.cpp.1 min readRead
Models335•07/13/2026, 09:15Enthusiast Reduces GLM-5.2 Language Model Size from 1.4TB to 980GB1 min readRead
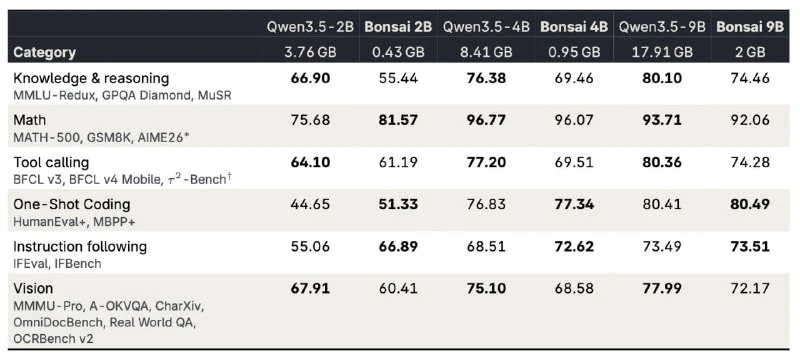
Models0•10/16/2026, 12:50PrismML expands Bonsai 2 with three compact AI models for local agents3 min readRead
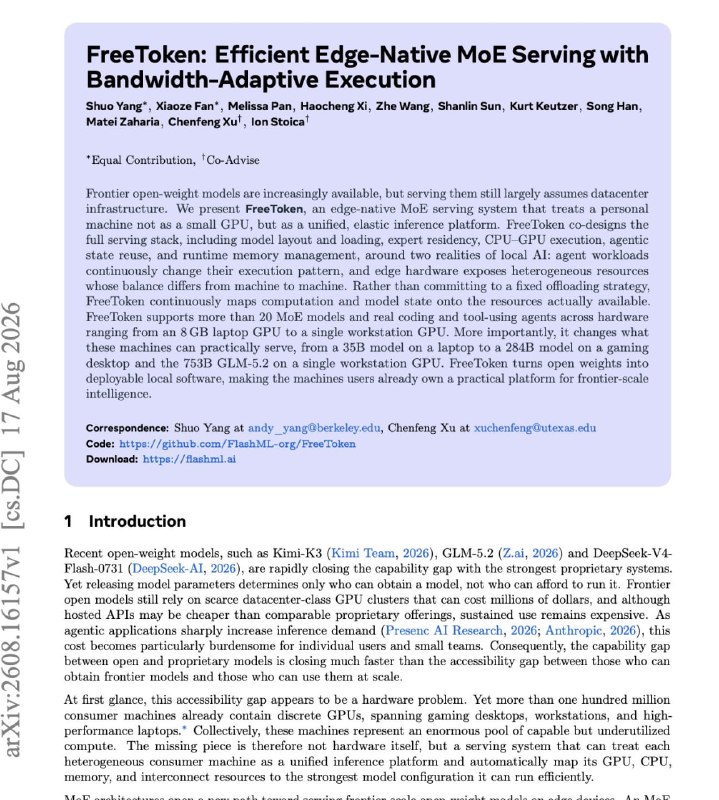
Models356•08/22/2026, 06:15FreeToken: A New System for Running Large MoE Models on Regular PCs3 min readRead