Release of the Day: MiMo-2.6 by Xiaomi — New Open SOTA Model
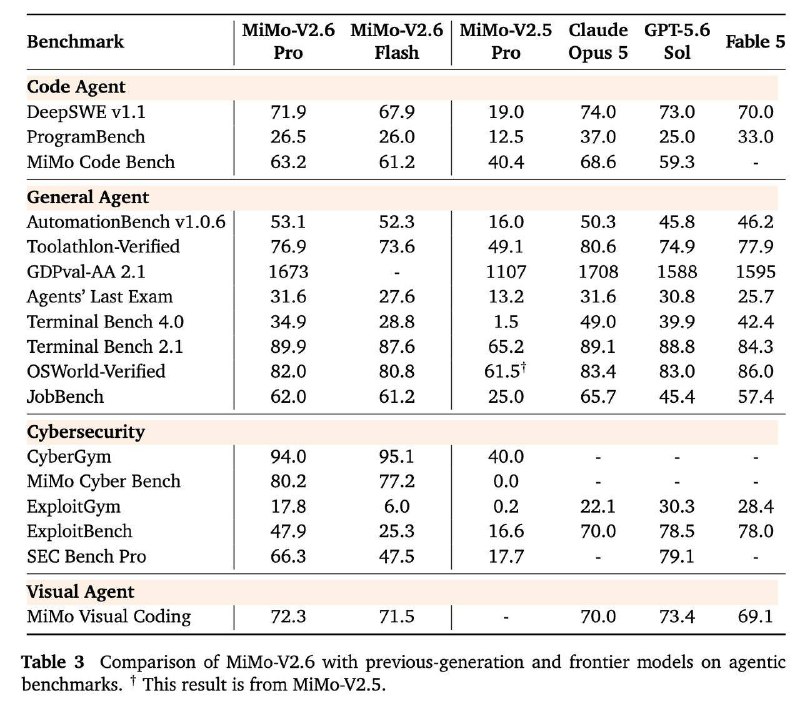
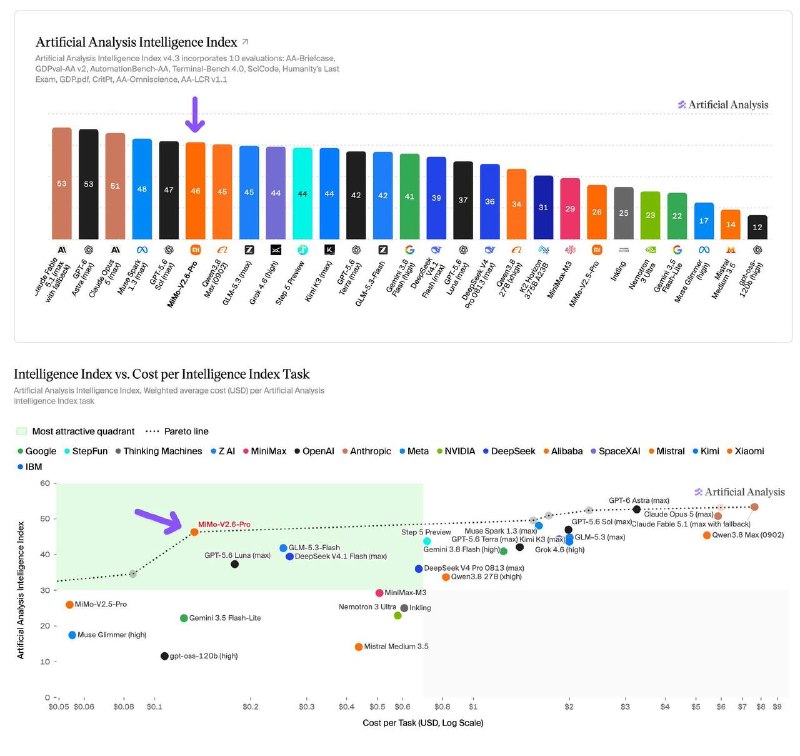
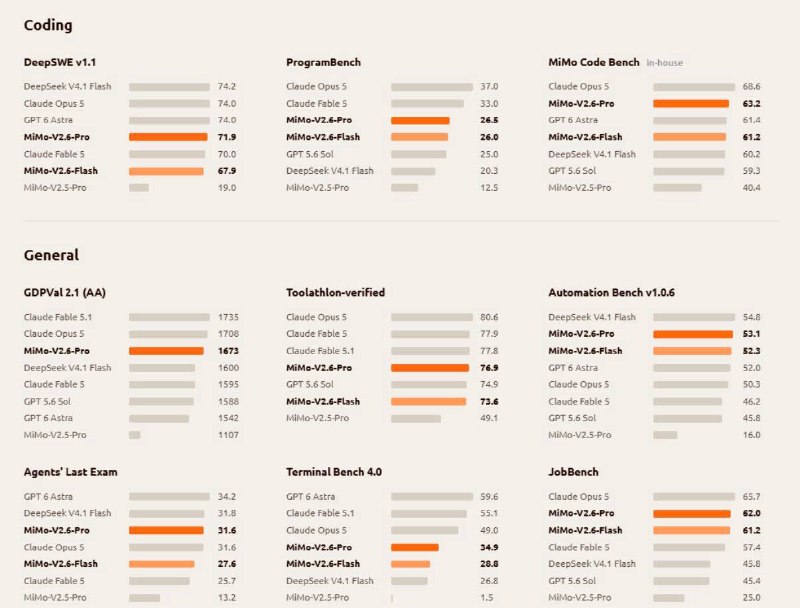
Xiaomi has released MiMo-2.6, an open multimodal model with a 1M token context that competes with top closed solutions while offering significantly lower costs.
Xiaomi has recently released MiMo-2.6, which appears to be the new open-source state-of-the-art (SOTA) model. According to developers, the Pro version performs on par with Claude Opus 5 and GPT-5.6 Sol in most agentic benchmarks (scoring 46 points in the Artificial Analysis Intelligence Index).
Architecturally, it is a MoE model with 1.02 billion parameters (42 billion active), featuring hybrid attention and a 5-layer MTP speculative decoder. This allows the model to predict multiple tokens ahead and verify their validity in parallel, providing a significant speed boost.
Key features:
- Context: Up to 1 million tokens.
- Multimodality: Native support.
- RL Scale: 750,000 RL trajectories for coding, vision, and CFT tasks.
- Asynchronous GRPO: The model tries 16 different solution paths for each task in parallel.
- Infrastructure: 7000+ RL agent environments are also open-sourced.
Training cost was only $3 million thanks to the use of verifiable tasks without labeling.
API Pricing:
- Pro: $0.435 / M input, $0.87 / M output
- Flash: $0.14 / M input, $0.28 / M output
Why it matters
AnalysisThe release of MiMo-2.6 reinforces the trend of accessible top-tier AI models via open source, lowering the barrier for agent developers due to low inference and training costs.
Discuss in community
Share your questions and insights with developers
Related in Ecosystem
Practical guides, core terminology, and agent skills
Thinking Machines Releases Inkling 2 Small: a 594B MoE Model That Can Fine-Tune Other Models
Thinking Machines released Inkling 2 Small, a 594B-parameter MoE model that leads among open models in several benchmarks and demonstrated autonomous fine-tuning of Qwen3.5-4B.
Thinking Machines releases Inkling 2 Small: a MoE model that competes with larger flagships
Thinking Machines introduced Inkling 2 Small, a multimodal Mixture-of-Experts model with 594B total parameters and 17B active per token. Full weights are promised next week under Apache 2.0.
Part II. AI Agent Architecture: From Model to Memory and Tools
A deep engineering dive: tokenization, KV-cache, sampling determinism, the training stack, quantization, context engineering, the safety stack, production RAG, ReAct, and multi-agent swarm systems.
Frontier Models
The most powerful class of artificial intelligence at the forefront of global research (Claude 3.7 Sonnet, OpenAI o3/GPT-4.5, Gemini 2.0 Pro), defining the limits of modern reasoning, autonomy, and coding capabilities.