Claude now self-assesses potentially harmful requests
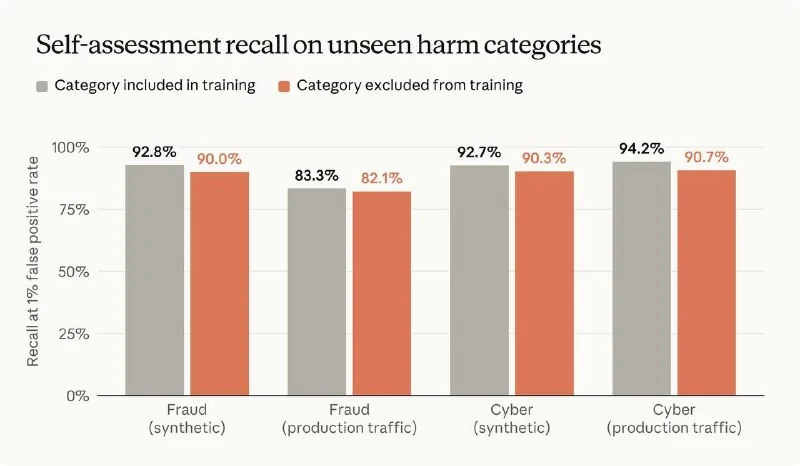
Anthropic says Claude receives a hidden instruction after each response to briefly evaluate whether the conversation contained a potentially harmful request.
Immediately after answering, the model receives a hidden instruction and briefly assesses whether the conversation contained a potentially harmful request.
The method is already active in all models starting with Fable 5 for most traffic, except for clients with zero data retention. On its own, it does not block anything; it only flags dialogues.
Why it matters
AnalysisIt shows how AI providers are embedding internal safety review directly into model responses, creating a lightweight monitoring layer without immediate blocking.
Discuss in community
Share your questions and insights with developers
Related in Ecosystem
Practical guides, core terminology, and agent skills
Anthropic trains Claude to mimic safety classifier without consulting policies
Claude now silently checks whether its responses may have contributed to harm, while Anthropic distills an expensive safety classifier into a cheaper self-assessment mechanism.
Chinese forum users claim to have decoded Claude account ban scoring system
Users allege Anthropic assigns initial points to new Claude accounts and deducts them for changing IPs, devices or proxies, subscribing to Max too early, or using only the web version.
Computer Use via AI
Anthropic's technology (introduced in Claude 3.5 Sonnet) enables neural networks to control operating systems like a human: taking screenshots, analyzing window coordinates, moving the mouse cursor, clicking buttons, and entering text without using specialized APIs.
Constitutional AI (RLAIF)
A behavior alignment method developed by Anthropic (creators of Claude). Instead of relying on millions of hours of human labor, the model critiques and corrects its own responses based on a clear set of ethical principles ('Constitution').