The New York Times sues Brave over scraping and reselling content for AI
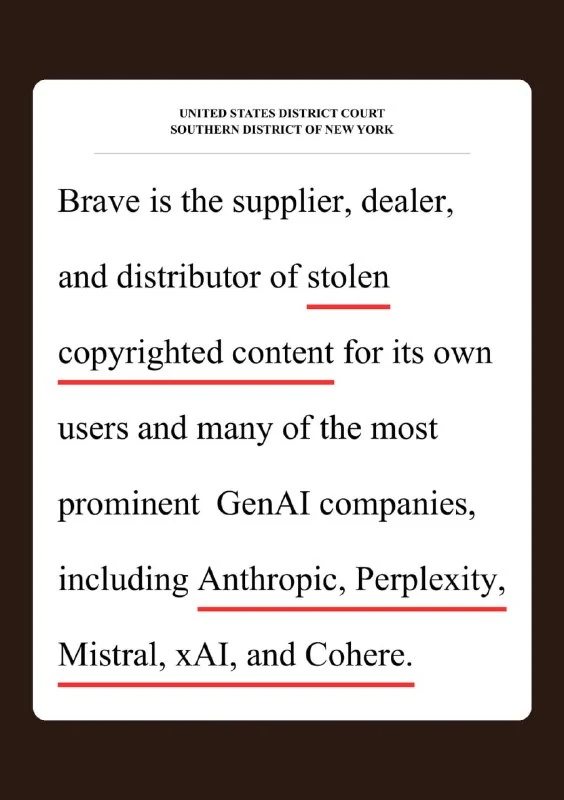
The New York Times accused Brave of copying billions of web pages and reselling a search index to AI developers such as Anthropic, xAI and Perplexity.
The New York Times filed a lawsuit against Brave, accusing the company of stealing journalistic material and reselling it to AI developers, including Anthropic, xAI and Perplexity.
According to the plaintiff, Brave copied more than 30 billion web pages using a crawler whose name was not disclosed. As a result, websites could not block it, and the resulting search index was later sold to AI companies.
In 2023, Brave wrote on its blog that Anthropic had used its search API to train Claude 2.
The New York Times also highlighted the Paywall blocker feature in the Brave browser, which was advertised as a way to bypass paid access to publications.
The plaintiff estimates that Brave earned more than $100 million from reselling third-party content, while publishers received nothing.
Why it matters
AnalysisThe lawsuit highlights a growing legal and ethical fault line in AI development: who owns training data, and how much control publishers can retain when crawlers bypass paywalls.
Discuss in community
Share your questions and insights with developers
Related in Ecosystem
Practical guides, core terminology, and agent skills
Hermes Profile: Corporate Legal Counsel & Contract Audit
Hermes Legal Ops profile: NDA and MSA/SOW contract reviews, redline comparison, SLA validation, liability detection, and compliance auditing.
Copyright and AI
The legal status of intellectual property for content generated by neural networks. Precedents from the US Copyright Office and EU: lack of copyright on pure generative outputs, the status of training on third-party works (Fair Use), and licenses for open models.
Open Weights vs Truly Open Source AI
A legal and engineering analysis of the fundamental difference between accessible numerical weights of models (Llama, DeepSeek) and fully open projects with source data, code, and architecture (OSI Standard).
Claude + Notion for Business: Automating CRM, Tasks, and Content in 30 Minutes
A step-by-step B2B guide to integrating Claude with Notion: ready-to-use database architecture, triggers, formulas, automation scripts, and prompt templates.