OpenAI launches GPT-6 Sol and Luna: Price cuts and improved caching
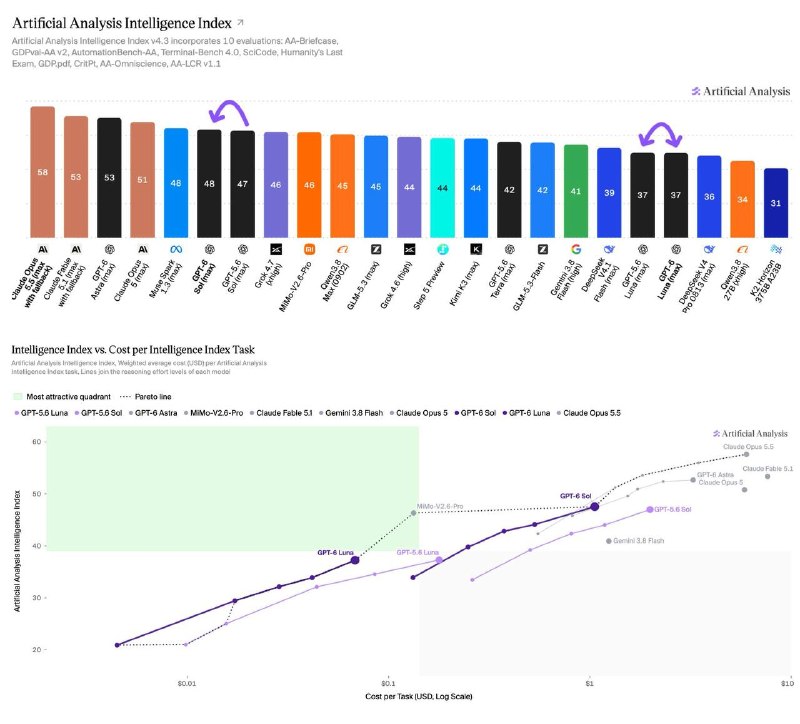
OpenAI has released GPT-6 Sol and Luna, significantly reducing costs and enhancing caching mechanisms. Sol competes with Claude Fable 5.1 in coding tasks but at a much lower price point.
OpenAI has introduced its new models, GPT-6 Sol and Luna, continuing the trend of price reductions previously initiated by Anthropic.
Pricing Changes
The costs for the new models have been significantly revised:
- Sol: Prices have been halved.
- Luna: Prices have dropped by approximately 50-58%.
Coding Performance
According to benchmarks, Sol does not appear to be outperformed by the new Opus in coding tasks. Metrics are comparable to Claude Fable 5.1:
- In FrontierCode, Sol matches Claude Fable 5.1 xhigh.
- In DeepSWE, Sol scores 68.8%, while Fable 5 scores 69.9%. However, Sol is approximately 80% cheaper.
- Luna (max mode) achieves 66.6%, which is at the level of Opus 5 and Fable 5 (medium), but with a cost 93–96% lower.
Improved Caching
OpenAI has significantly enhanced its caching system:
- Higher hit rate.
- The discount for cached input is now 90%.
- Added dashboard and diagnostics tools.
- Cache no longer resets when changing the
reasoning effortparameter or toggling tools on/off.
Availability
The models are already available in subscriptions and via the API. Luna is also offered for free.
Why it matters
AnalysisPrice cuts and improved caching make OpenAI's advanced AI models more accessible to developers, while competitive coding performance puts pressure on other labs.
Discuss in community
Share your questions and insights with developers
Related in Ecosystem
Practical guides, core terminology, and agent skills
GPT-6 Astra: Guide to OpenAI's New Model
Comprehensive overview of OpenAI's flagship GPT-6 Astra: agentic architecture, Computer Use capabilities, software engineering in Codex, cybersecurity benchmarks, prompt engineering tips, and API migration guide.
Prompt Caching & KV Cache Reuse
A technology utilized by modern inference engines and cloud APIs (Anthropic, OpenAI, DeepSeek, vLLM) that stores precomputed attention matrices (KV Cache) of static prefixes, reducing processing costs by 80–90% and decreasing time to first token (TTFT) by 4–8 times.
Prompt Caching Architecture & Economics
A methodology for designing prompts focused on maximizing hardware cache hits for prefixes (Prefix Caching) in Anthropic, OpenAI, and DeepSeek, achieving a 90% cost reduction and 80% speedup.
OpenAI adds outbound phone call support to GPT-Live API
OpenAI has added official support for outbound SIP calls in the GPT-Live API, enabling developers to build voice AI agents that call people in real time.