DeepSeek Harness: High Efficiency in Token Usage
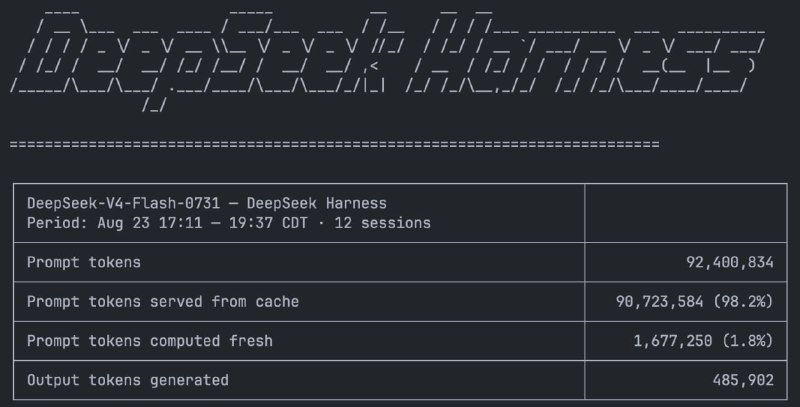
DeepSeek Harness shows impressive results with 98.2% cache hits, allowing for token savings. The GitHub repository is rapidly gaining popularity.
DeepSeek Harness: High Efficiency in Token Usage
After several hours of working with the self-deployed DeepSeek V4 Flash 0731, the standout feature is the 98.2% cache hit rate. This is a huge figure that indicates the system's high efficiency.
Thanks to this efficiency, the system uses tokens very economically, which is an important aspect for users.
The GitHub repository has already gained 188,000 stars in less than two weeks, indicating significant interest in this tool.
Why it matters
AnalysisThis tool allows for significant reductions in token costs, which is critical for developers and researchers in the AI field. Its high popularity on GitHub indicates its potential within the community.
Discuss in community
Share your questions and insights with developers
Related in Ecosystem
Practical guides, core terminology, and agent skills
DeepSeek launches Creator Mode to let users reshape their harness
DeepSeek’s open-source harness now supports Creator Mode, where an agent can write and embed plugins based on plain-language descriptions.
Top GitHub Repositories for SEO and Keyword Research
8 battle-tested open-source GitHub repositories for semantic keyword discovery, technical audits, and Generative Engine Optimization (GEO).
Six DeepSeek Harness Plugins to Cut Token Usage and Organize Context
A review of six plugins for DeepSeek Harness, covering free model access, memory organization, agent routing, and context monitoring.
DeepSeek (Chinese Breakthrough in Open AI)
A series of groundbreaking open models from the Chinese lab DeepSeek (V3, R1). Demonstrates top-tier coding and reasoning capabilities at a cost 10–20 times lower than Western commercial counterparts.