# CSV Format: The Complete Guide for AI Workflows and Automation
> A comprehensive hands-on guide to using CSV in AI data pipelines: RFC 4180 specifications, comparison with XLSX and JSON, bulk cleaning, Python/TypeScript automation, and production prompt templates.
## 1. What Is the CSV Format: Anatomy, RFC 4180 Specification, and Data Architecture
**CSV** (*Comma-Separated Values*) is the world's most ubiquitous open text format for storing and exchanging two-dimensional tabular data. Its formal specification is codified under the IETF standard RFC 4180.
At its core, a CSV file is plain text stripped of visual overhead: each file line represents one tabular record (row), while horizontal cell values are delimited by commas. Typically, the very first row serves as the column header schema.
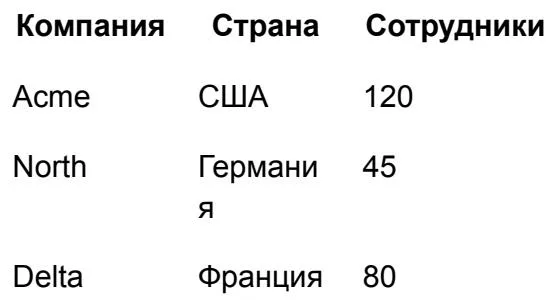
```csv
Company,Country,Employees
Acme,USA,120
North,Germany,45
Delta,France,80
```
### Core Formatting Invariants Under RFC 4180
1. **Line Terminators:** Each record resides on a separate line terminated by standard line feeds (`CRLF` or `LF`).
2. **Mandatory Quotes:** Any field value containing a comma, a line break, or double quotes must be fully enclosed in double quotation marks: `"New York, NY"`.
3. **Quote Escaping:** Internal quotation marks within a string must be escaped by doubling them: `"Acme ""Advanced"" Solutions"`.
4. **Column Count Uniformity:** Every subsequent record row must maintain the exact same column count defined in the initial header row.
> [!NOTE]
> CSV files preserve pure data values exclusively. They store zero font data, cell background colors, column width coordinates, or computational formulas. This extreme minimalism is precisely what makes CSV the universal bridge between AI models, SQL databases, and SaaS APIs.
---
## 2. Why CSV Is the Most Token-Efficient Format for LLMs and AI Agents
Modern Frontier LLMs (GPT-4o, Claude 3.5 Sonnet, Gemini 1.5 Pro) can parse both CSV and XLSX workbooks. However, across automated software pipelines and autonomous agents, CSV remains the default industry transport mechanism.
```mermaid
flowchart LR
A["Raw Unstructured Text
(Reviews, leads, tickets)"] --> B["LLM / AI Agent
(Entity parser & classifier)"]
B -->|Generates flat text stream| C["CSV Data Stream
(Minimal token overhead)"]
C --> D["SQL / NoSQL Databases
(High-throughput bulk import)"]
C --> E["CRM / BI Dashboards
(HubSpot, Tableau, Sheets)"]
```
### Core Advantages for Artificial Intelligence Systems
- **Exceptional Token Conservation:** Unlike XLSX (a zipped archive of dozens of verbose XML sheets) or JSON (which repeats every attribute key for every single array element), CSV defines field keys exactly once in the header.
- **Minimal Context Window Latency:** Large language models reason through flat delimiters without wading through nested tags or styling metadata.
- **Native Streaming Ingestion:** AI backends can generate and stream CSV responses line-by-line in real time, processing multi-gigabyte datasets in modular chunks.
- **Seamless Code Interpreter Compatibility:** Data analysis sandboxes in ChatGPT and Claude execute instant dataset analysis with a single `pandas.read_csv()` invocation.
---
## 3. Comparative Matrix: CSV vs. XLSX vs. JSON
Selecting the correct format depends on whether you require bare tabular records, multi-tab computational spreadsheets, or complex nested trees.
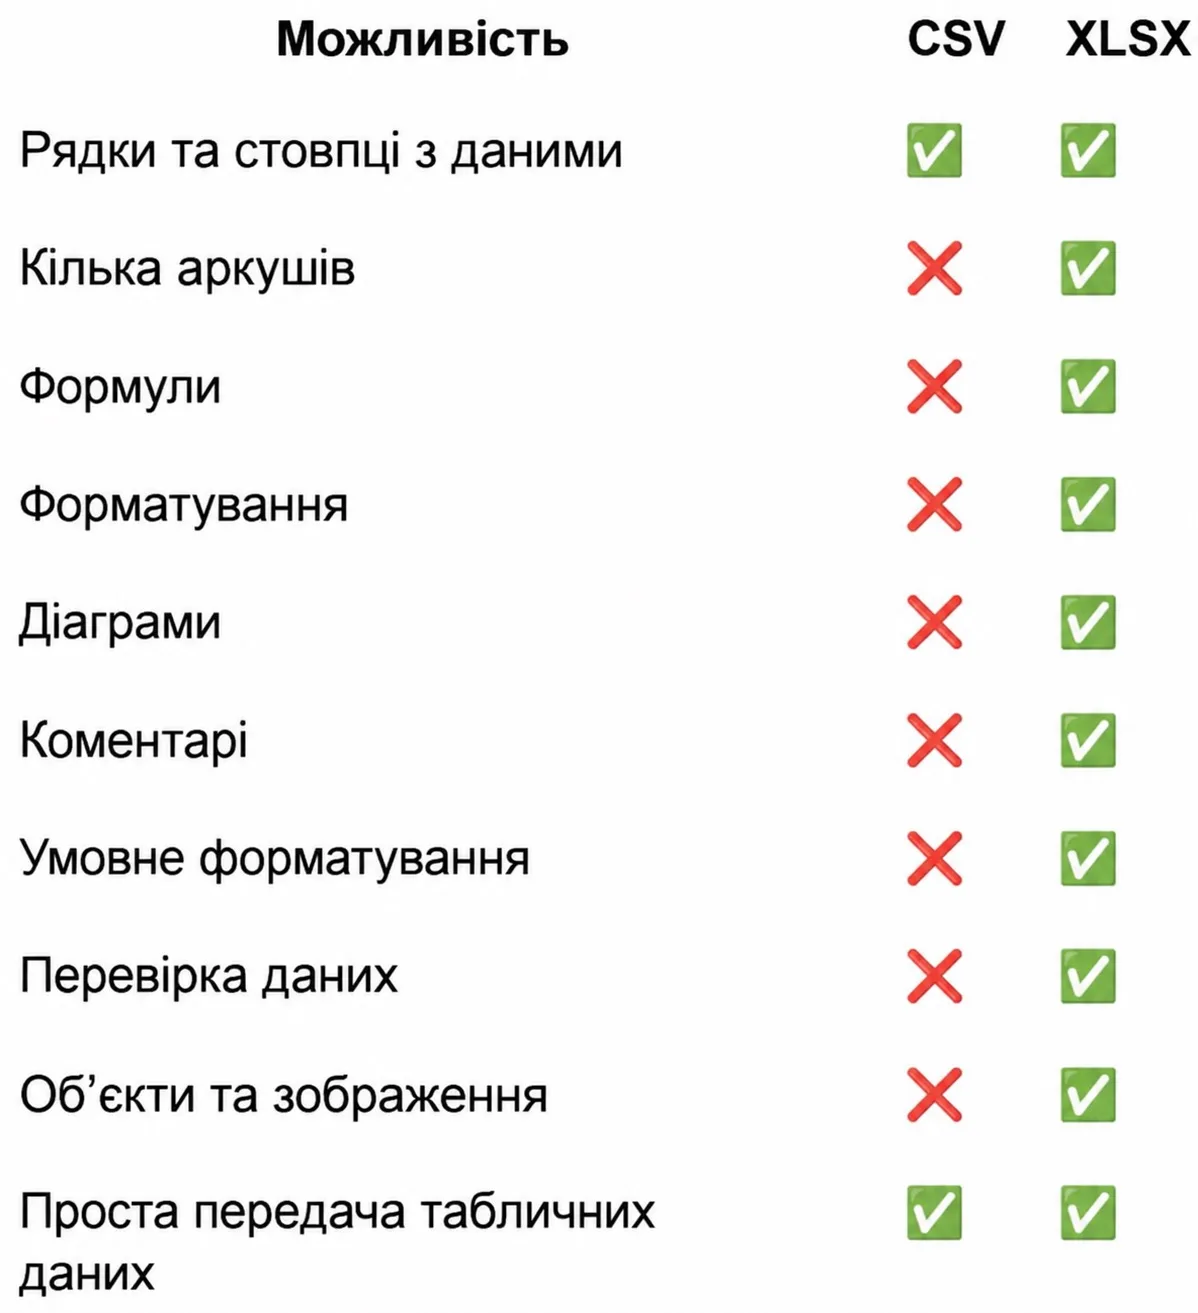
| Architectural Feature | CSV | XLSX (Excel) | JSON |
| :--- | :--- | :--- | :--- |
| **Tabular Rows & Columns** | ✓ Yes | ✓ Yes | Requires flat normalization |
| **Multiple Named Worksheets** | ✗ No (Single flat sheet) | ✓ Yes | ✓ Via nested array keys |
| **Computational Formulas** | ✗ No | ✓ Yes (Live calculation engine) | ✗ No |
| **Cell Styling & Formatting** | ✗ No | ✓ Yes (Colors, fonts, widths) | ✗ No |
| **Hierarchical Nested Data** | ✗ Poor (Flattens structures) | ✗ Limited | ✓ Native object trees |
| **AI Token Efficiency** | ⭐ Highest | ⚠️ Lowest (Heavy XML overhead) | 🟡 Moderate (Key redundancy) |
| **Direct CRM / DB Bulk Import** | ✓ One-click native import | ⚠️ Requires pipeline conversion | ⚠️ Requires custom mapping |
> [!TIP]
> Use CSV whenever your primary goal is mass data transformation, tabular classification, or database migration. Preserve XLSX only when communicating financial models to humans who depend on live formula recalculations.
---
## 4. Common Syntax Pitfalls: Delimiters, Quoting Rules, and UTF-8 Encodings
Despite its deceptive simplicity, over 70% of automated CSV ingestion failures stem from three technical edge cases.
### The Comma vs. Semicolon Collision (European Locales)
In many European countries, the standard decimal separator is a comma (`12,50`). Consequently, regional desktop Excel installations default to exporting CSV files delimited by semicolons (`;`) rather than standard commas (`,`).
- If an AI model expects commas but receives semicolons, it treats entire rows as single concatenated strings.
- Always include an explicit delimiter instruction in your prompt: *“Use standard comma-delimited formatting”*.
### Multiline Line Breaks Within Cell Values
When descriptive text contains paragraph breaks, poorly configured parsers interpret each newline as a brand-new table row. Under RFC 4180, multiline cells must be strictly wrapped inside double quotes:
```csv
ID,Title,Description
101,Laptop,"High performance CPU.
Includes 24-month warranty."
```
### UTF-8 Character Encoding and the BOM Signature
Opening Cyrillic or multilingual CSV files in older Windows Excel versions frequently results in corrupted characters. This occurs when the file lacks a **BOM** (*Byte Order Mark* — the three bytes `EF BB BF`).
- For modern cloud databases and AI APIs, output clean **UTF-8 without BOM**.
- If the file is specifically destined for legacy desktop Excel on Windows, export as **UTF-8 with BOM**.
---
## 5. Preparing CSV for AI: Data Sanitation and Cleanliness Protocols
The analytic accuracy of an LLM is directly proportional to the structural cleanliness of its input dataset.
```mermaid
flowchart TD
subgraph Hygiene_Rules["5 Golden Rules of CSV Hygiene"]
R1["1. Semantic Header Keys
('company_name' over 'Col1')"]
R2["2. Atomic Values
(Separate 'first_name' and 'email')"]
R3["3. Continuous Data Arrays
(Zero empty decorative gap rows)"]
R4["4. Canonical Data Types
(ISO 8601 'YYYY-MM-DD', raw floats)"]
R5["5. One Entity Per Row
(Strict 2D tabular normalization)"]
end
```
### Before and After Data Sanitation
:::tabs
@tab Unsanitized CSV (Poor)
```csv
Monthly Summary Report May 2026,,,
Company,Contact Details,Spend
Vector LLC,"Kyiv, Ivan, phone: +380501112233",5000 UAH
Alpha Inc,Odessa; Peter,12000 $
```
*Flaws:* Extraneous header banner, empty spacer row, concatenated contact data, mixed currency representations.
@tab Sanitized CSV (Production-Ready)
```csv
company_name,city,contact_name,phone,amount,currency
Vector LLC,Kyiv,Ivan,+380501112233,5000,UAH
Alpha Inc,Odessa,Peter,+380502223344,12000,USD
```
*Strengths:* Atomic attributes, clean numeric floats, standardized currency codes, immediate zero-friction parsing.
:::
---
## 6. Batch Data Processing: Automated Cleaning, Enrichment, and Classification
CSV delivers its highest ROI when orchestrating bulk data transformations through ChatGPT Advanced Data Analysis or Claude Code.
### Primary Production Automation Scenarios
1. **Deduplication & Entity Resolution:** Merging duplicate company profiles (e.g. *“Google LLC”* and *“Google Inc”*) and filtering corrupted contact rows.
2. **Automated Attribute Enrichment:** Scanning raw company lists to infer industry verticals, estimated revenue tiers, or country codes.
3. **Sentiment & Intent Tagging:** Ingesting 10,000 customer feedback comments to append structured `Sentiment` (*Positive/Neutral/Negative*) and `Category` (*Billing/Product/Bug*) attributes.
4. **Canonical Geographic Normalization:** Harmonizing disparate country strings (*“USA”, “U.S.”, “United States”, “America”*) into ISO alpha-2 codes (`US`).
---
## 7. When CSV Is the Wrong Choice: Architectural Limitations and Alternatives
CSV is a specialized tool. Misapplying it to multidimensional data structures causes severe architecture breakdowns.
### Four Critical Constraints of CSV
1. **Complex One-to-Many Relationships:** Storing a client with 5 shipping addresses, 3 payment methods, and 20 line-item orders inside a flat CSV row leads to unmanageable duplication. Use **JSON** for hierarchical schemas.
2. **Formula Auditing & Logic Modeling:** If you need to trace how modifying an assumption in cell `B2` impacts EBITDA in `G48`, rely on **XLSX**. CSV strips all calculation logic, leaving only static numbers.
3. **Customer-Facing Business Documents:** Proposals, formal agreements, and operational SOPs require page numbering, corporate typography, and logos. These belong in **DOCX**.
4. **Unstructured Knowledge & Articles:** Reports, research papers, and technical guides lose context when coerced into tables. Maintain them in **Markdown**.
---
## 8. Programmatic Automation: Working with CSV in Python and TypeScript
In autonomous production agents, CSV processing is handled by high-performance libraries that stream records without memory spikes.
:::tabs
@tab Python (Pandas & Streaming)
```python
import pandas as pd
# 1. High-throughput ingestion and data filtering
df = pd.read_csv("clients.csv", encoding="utf-8")
# Data cleaning and column addition
df_cleaned = df.dropna(subset=["email"]).copy()
df_cleaned["status"] = "Active"
# 2. Memory-safe streaming for large datasets (>1 GB)
chunk_size = 5000
for chunk in pd.read_csv("massive_dataset.csv", chunksize=chunk_size):
# Pass chunk to model or filter pipeline
processed_chunk = chunk[chunk["revenue"] > 10000]
processed_chunk.to_csv("filtered_data.csv", mode="a", header=False, index=False)
print("Batch processing complete.")
```
@tab TypeScript (Papaparse & Node.js)
```typescript
import Papa from 'papaparse';
import * as fs from 'fs';
interface CompanyRecord {
company: string;
country: string;
employees: number;
priority?: string;
}
// Read raw file stream
const fileContent = fs.readFileSync('companies.csv', 'utf8');
Papa.parse(fileContent, {
header: true,
dynamicTyping: true,
skipEmptyLines: true,
complete: (results) => {
// Enrich each row via AI inference logic
const enriched = results.data.map(row => ({
...row,
priority: row.employees > 100 ? 'High' : 'Standard'
}));
// Reserialize clean CSV payload
const csvOutput = Papa.unparse(enriched);
fs.writeFileSync('companies_enriched.csv', csvOutput, 'utf8');
}
});
```
:::
---
## 9. Battle-Tested Master Prompt Library for CSV Operations
Employ these structured prompt templates to extract and enrich datasets without dropped rows or malformed columns.
### Prompt for Generating a Dataset from Scratch
```markdown
Act as a senior data analyst. Generate a realistic synthetic dataset formatted in standard RFC 4180 CSV.
Topic: [Insert Topic, e.g. B2B SaaS Marketing Tool Directory 2026]
Volume: Exactly 25 unique records.
Structural Constraints:
- Columns: Tool_Name, Category, Pricing_Model, Target_Audience, Key_Feature, URL_Slug
- First row must contain English column names with zero spaces.
- Exactly one row per tool.
- Enclose all values containing commas inside double quotation marks.
- Return ONLY valid raw CSV code within a ```csv code fence. Zero introductory or concluding chatter.
```
### Prompt for Cleaning and Enriching an Existing Dataset
```markdown
Analyze the attached CSV file. Your objective is to audit, clean, and enrich the dataset.
Processing Rules:
1. Eliminate all exact duplicate rows.
2. Standardize the "Country" column into standardized international country names.
3. Append a new column named "Segment":
- "Enterprise" if Employees > 250
- "Mid-Market" if Employees is between 50 and 250
- "SMB" if Employees < 50
4. Append a column named "Action_Plan" containing a brief directive for the account manager (maximum 10 words).
5. Retain all original column positions and values without alteration.
Return the final cleaned output as a downloadable CSV artifact.
```
---
## 10. Pre-Flight Validation Checklist and Format Selection Decision Tree
Execute this rapid checklist prior to ingesting CSV payloads into production databases or CRM integrations.
### CSV Quality Assurance Checklist
- [ ] **Column Parity:** The count of delimiter commas matches across every row against the initial header count.
- [ ] **Enclosure Verification:** All text fields containing commas or line feeds are safely enclosed in double quotes `" "`.
- [ ] **Zero Decorative Spacers:** No empty separator rows exist in the header, body, or footer.
- [ ] **Character Encoding:** File is validated as UTF-8 (and verified for BOM compatibility if targeting desktop Windows Excel).
- [ ] **Uniform Data Types:** Dates adhere strictly to ISO 8601 (`YYYY-MM-DD`), and numeric floats use periods rather than decimal commas.
### Quick Decision Tree
- Raw tabular data for mass processing, filtering, or automated code $\rightarrow$ **CSV**.
- Living calculation models featuring formulas, charts, and multiple sheets $\rightarrow$ **XLSX**.
- Complex, multi-level nested data trees for API integrations $\rightarrow$ **JSON**.
- Polished, branded corporate documents for human reading and archiving $\rightarrow$ **DOCX**.